Publications
My work spans the stack, from reusable GPU primitives to algorithm–system co-design to complete serving systems, for both language models and multimodal generation. Browse it as a research tree that shows how the projects build on each other, or as a list of all papers.
Hover a project to trace what it builds on and what it powers; click it for details.
Language Models
Multimodal & Video Generation
SystemsServing, scheduling, and end-to-end engines
Algorithm–System Co‑designSparsity and quantization that run fast on real hardware
Primitives & KernelsReusable GPU building blocks
Edge Serving
FreeToken
Edge MoE serving
arXiv 2026 · 13.8k★
uses Graph-Compatible Cache
Cloud Serving
BlendServe
Offline inference
ASPLOS 2026
Prism
OSDI 2026
S-LoRA
MLSys 2024
UCCL
OSDI 2026
Streaming Generation
StreamDiffusionV2
MLSys 2026 Best Paper
Streaming system for real-time, interactive video generation.
SLO-aware batchingMulti-pipeline orchestrationMotion-aware noiseStream-VAE
Sparse Attention
DoubleSparse
Post-training sparsity
Merged into SGLang
in SGLang
HashAttention
ICML 2025
Twilight
NeurIPS 2025 Spotlight
vAttention
ICLR 2026
Sparse Video Attention
Sparse VideoGen
Space-time sparsity
ICML 2025
Sparse VideoGen2
Semantic permutation
NeurIPS 2025 Spotlight
uses Flash-KMeans
Radial Attention
NeurIPS 2025
SLA
ICLR 2026
KV Quantization
Quant VideoGen
2-bit KV cache
ICML 2026
uses Flash-KMeans
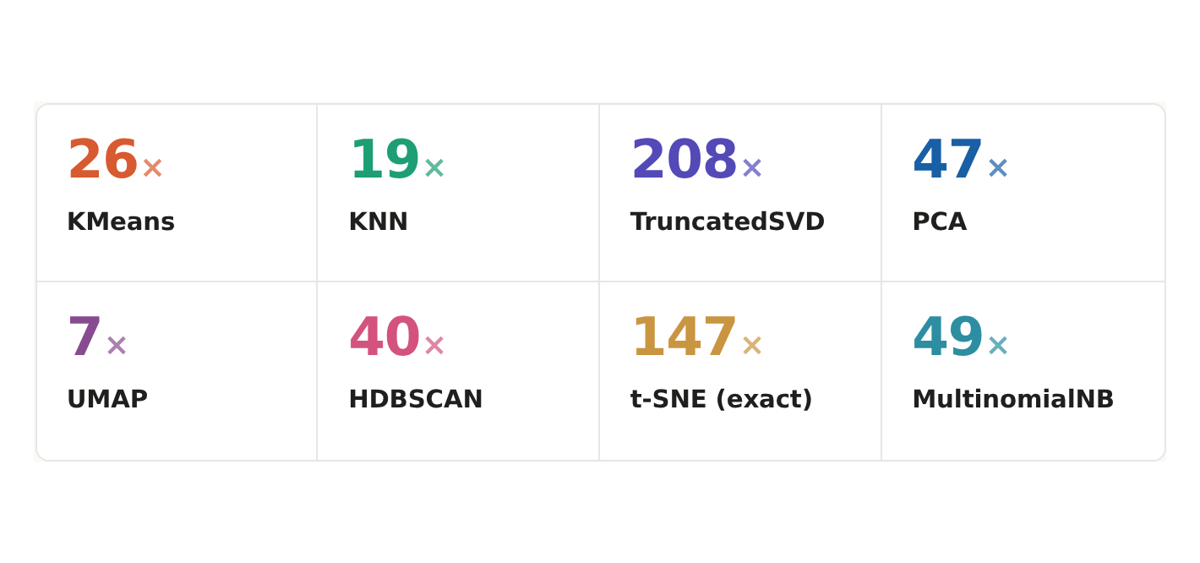
FlashLib18 classical ML primitives on GPU594★ · up to 208× over cuML
Flash-IVF-Flat
GPU ANN index
29× faster
Flash-KNN
Fused top-K search
19× over cuML
Graph-Compatible Cache
Cache for graph execution
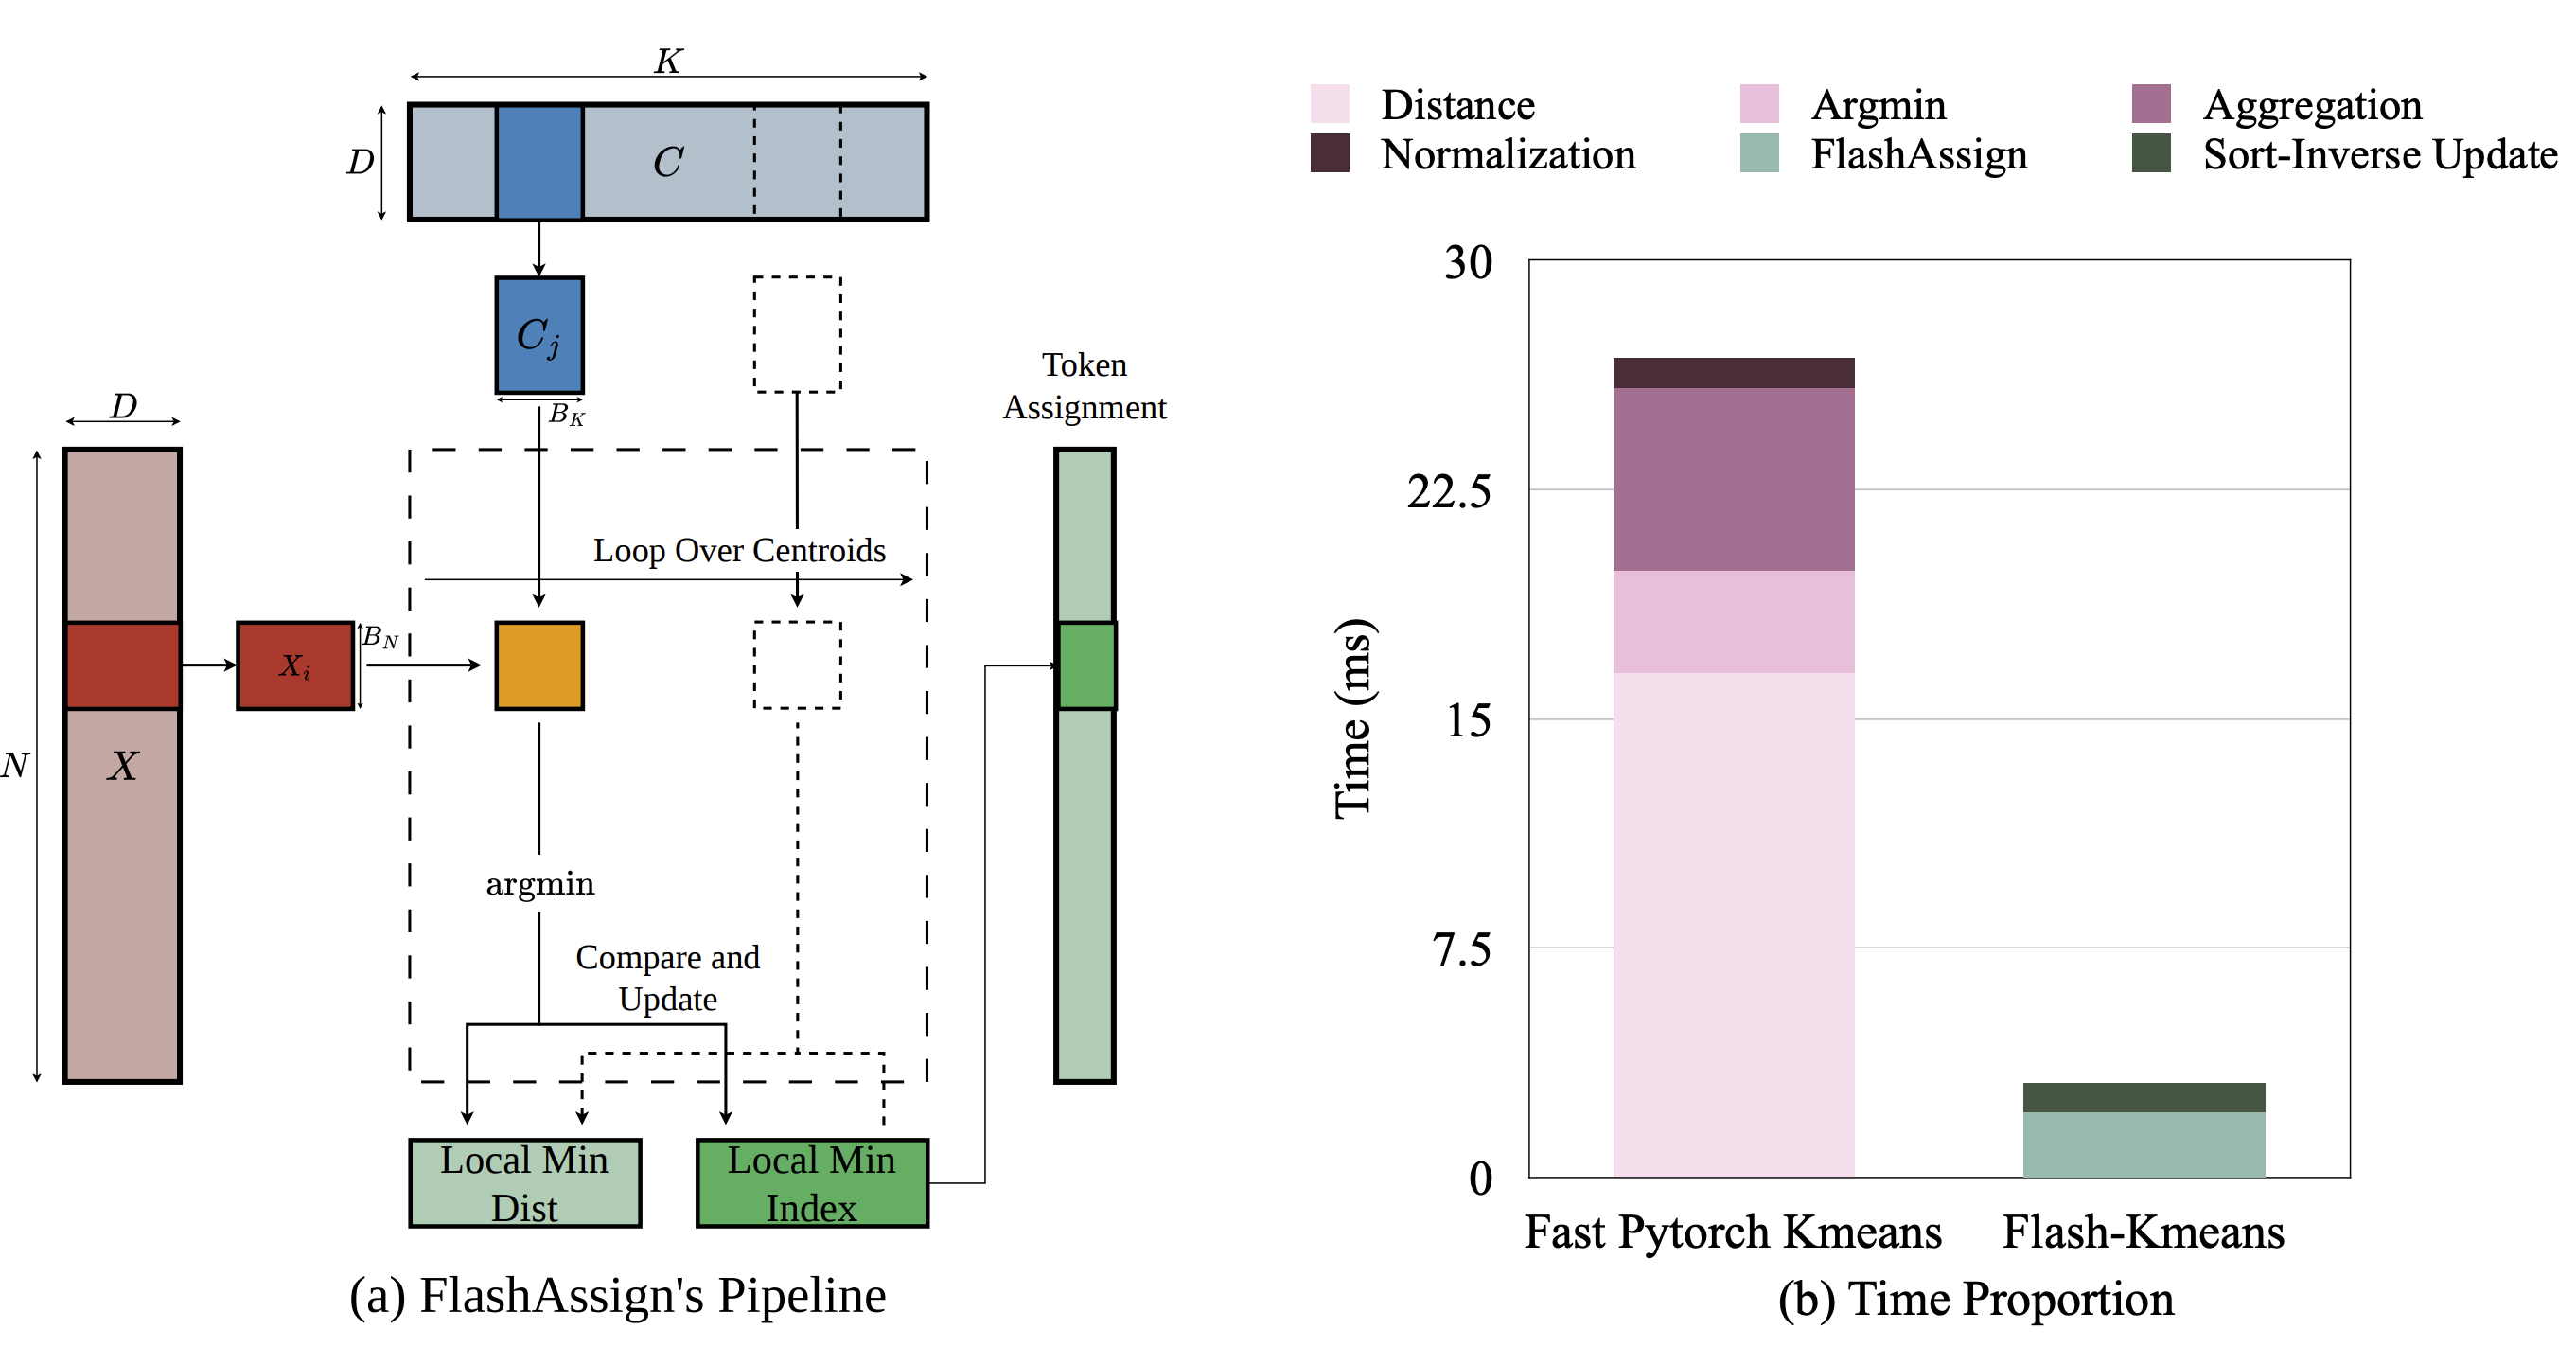
Flash-KMeans
Exact GPU K-Means
NeurIPS 2026 · 700+★
PCA · SVD
Decomposition
up to 208× over cuML
HDBSCAN · t-SNE
UMAP, regression, …
up to 147× over cuML
13.8k stars
Edge Serving
MoE
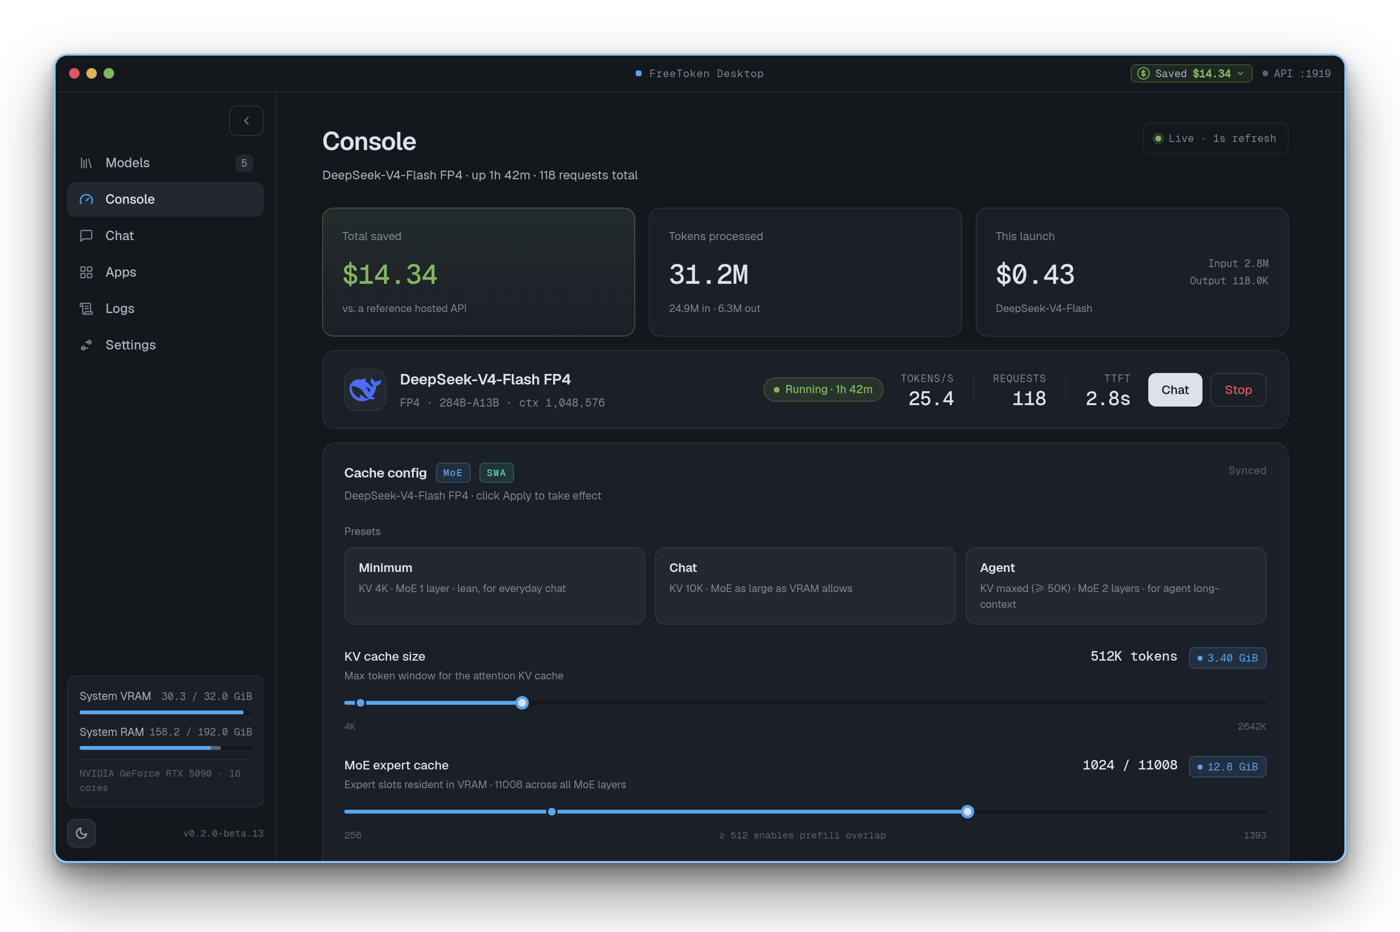
FreeToken
Efficient edge-native MoE serving with bandwidth-adaptive execution.
GPU Library
Classical ML Operators
Agent-Native API
FlashLib
Bringing flash magic to classical machine learning operators.
NeurIPS 2026
Exact K-Means
Kernel Optimization
Flash-KMeans
Fast and memory-efficient exact K-Means.
ICML 2026
Long Video
KV Cache
Quantization
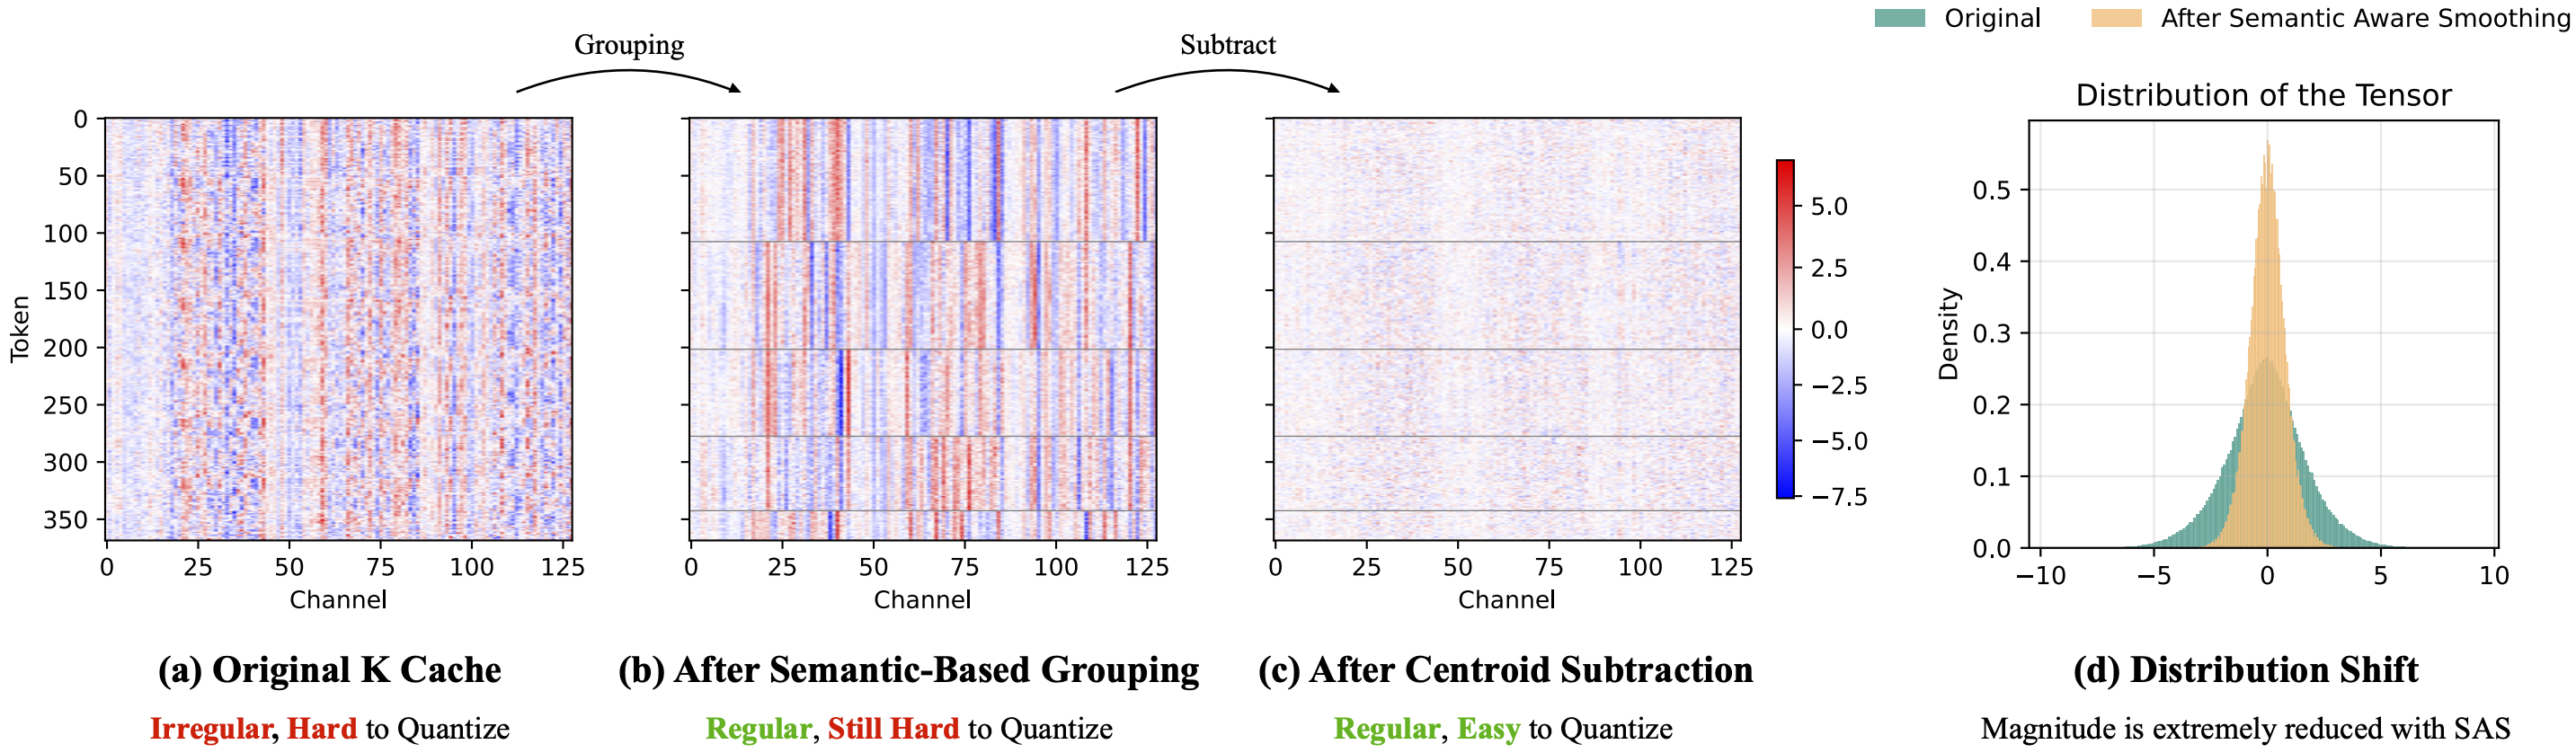
Quant VideoGen
Auto-regressive long video generation via 2-bit KV-cache quantization.
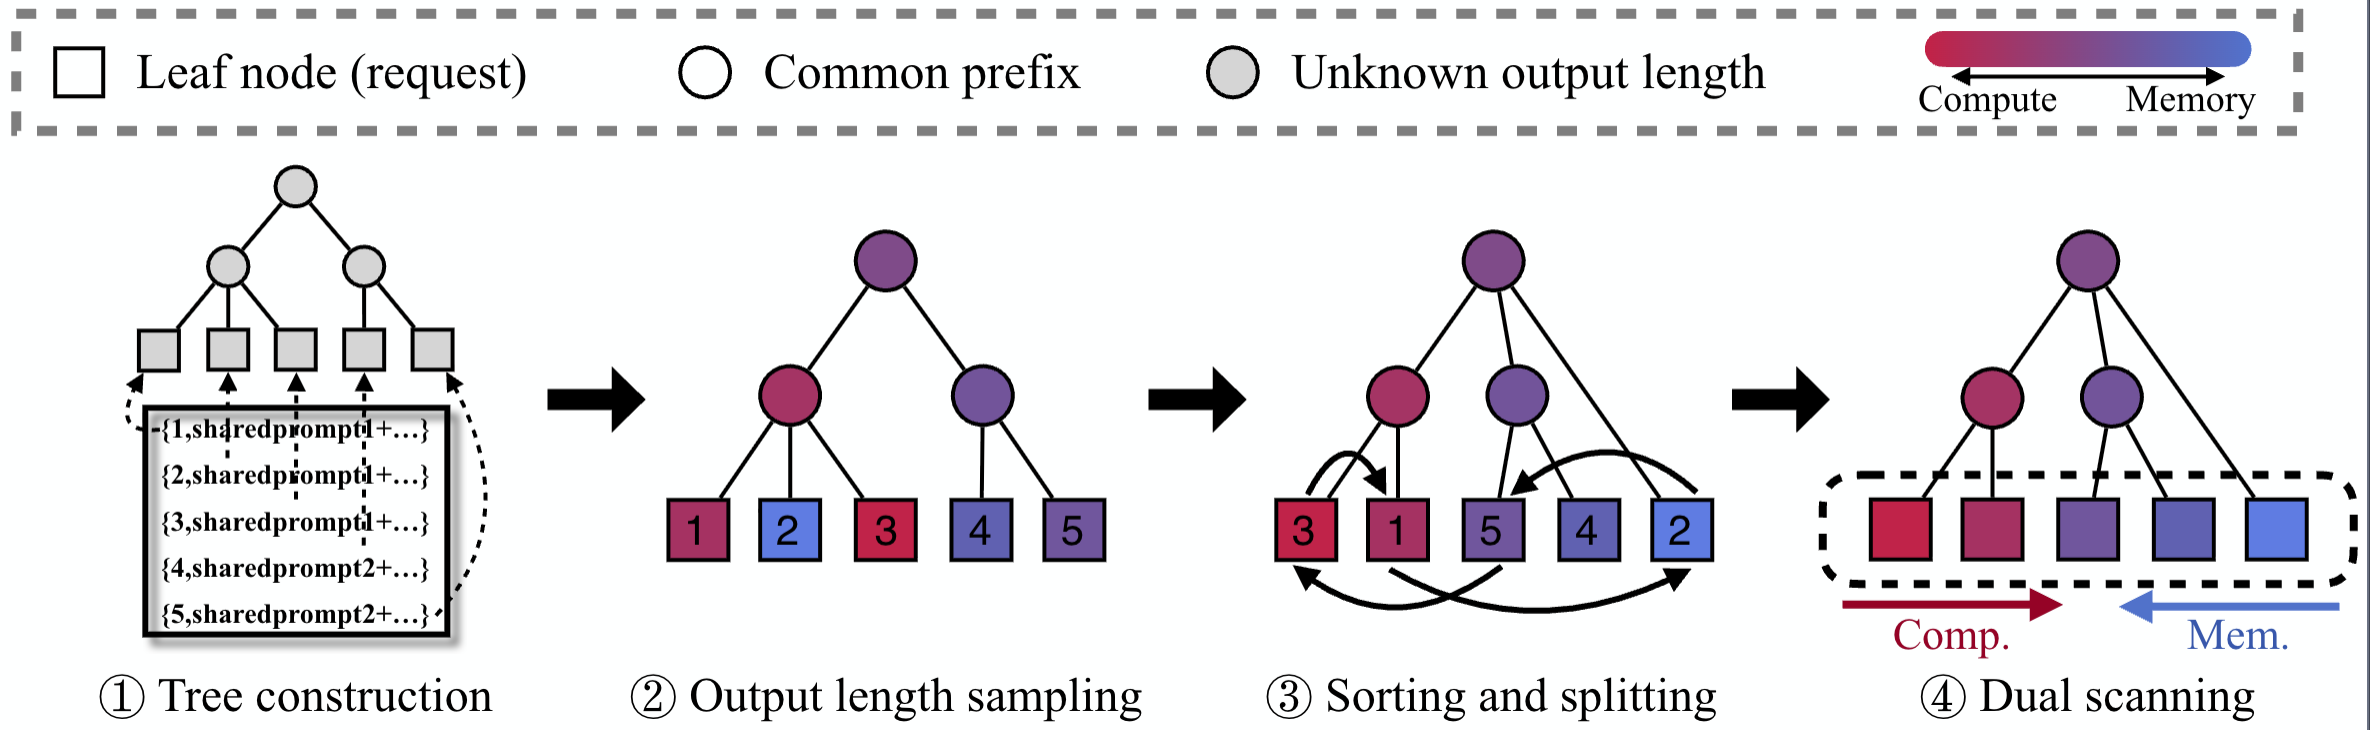
ASPLOS 2026
Offline Inference
LLM Serving
BlendServe
Optimizing offline inference for autoregressive large models with resource-aware batching.
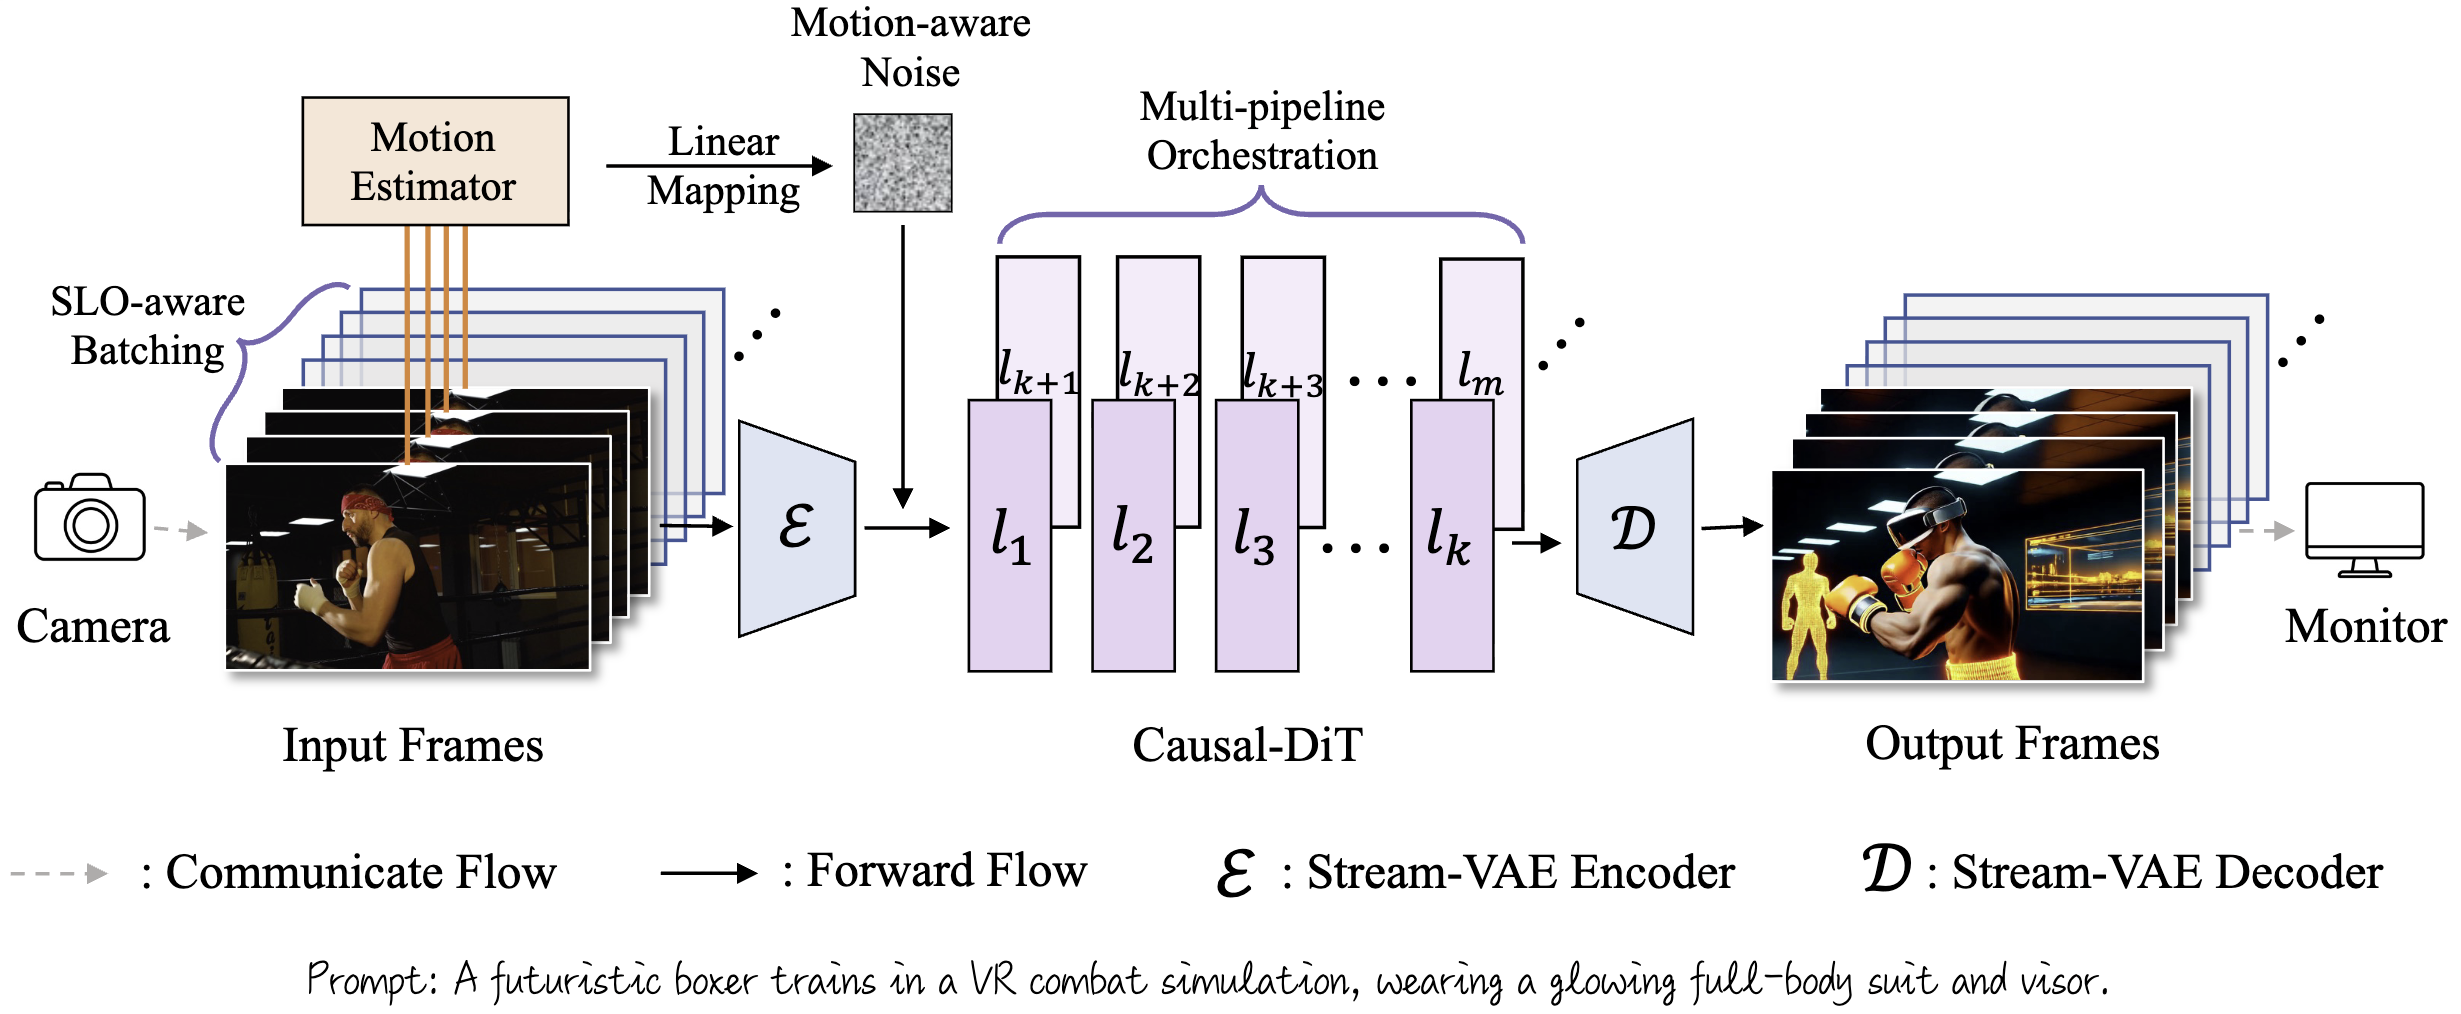
MLSys 2026 Best Paper
Interactive Video
Streaming System
StreamDiffusionV2
A streaming system for dynamic and interactive video generation.
ICLR 2026
Verified Sparsity
Sparse Attention
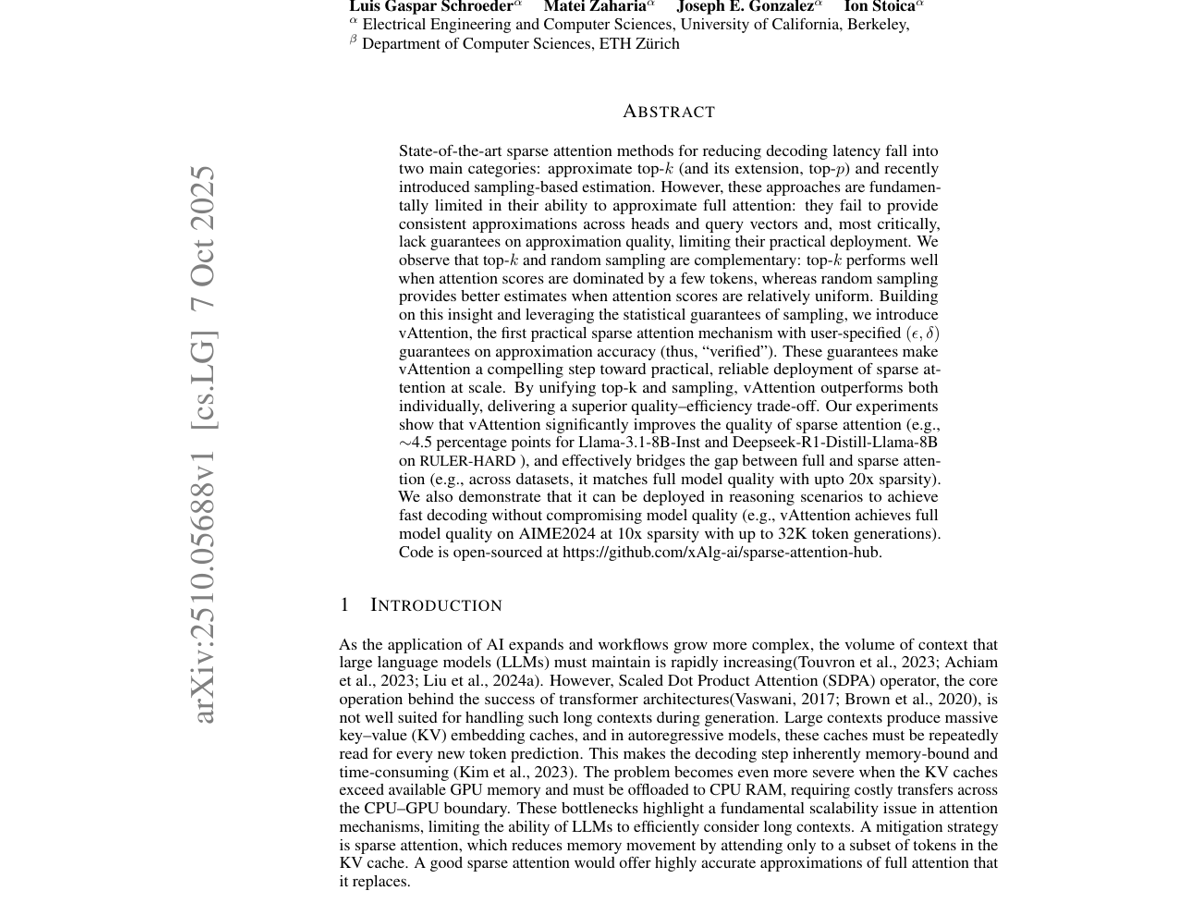
vAttention
Verified sparse attention.
ICLR 2026
Sparse-Linear Attention
Diffusion Transformers
SLA
Beyond sparsity in diffusion transformers via fine-tunable sparse-linear attention.
NeurIPS 2025 Spotlight
Semantic Permutation
Video Generation
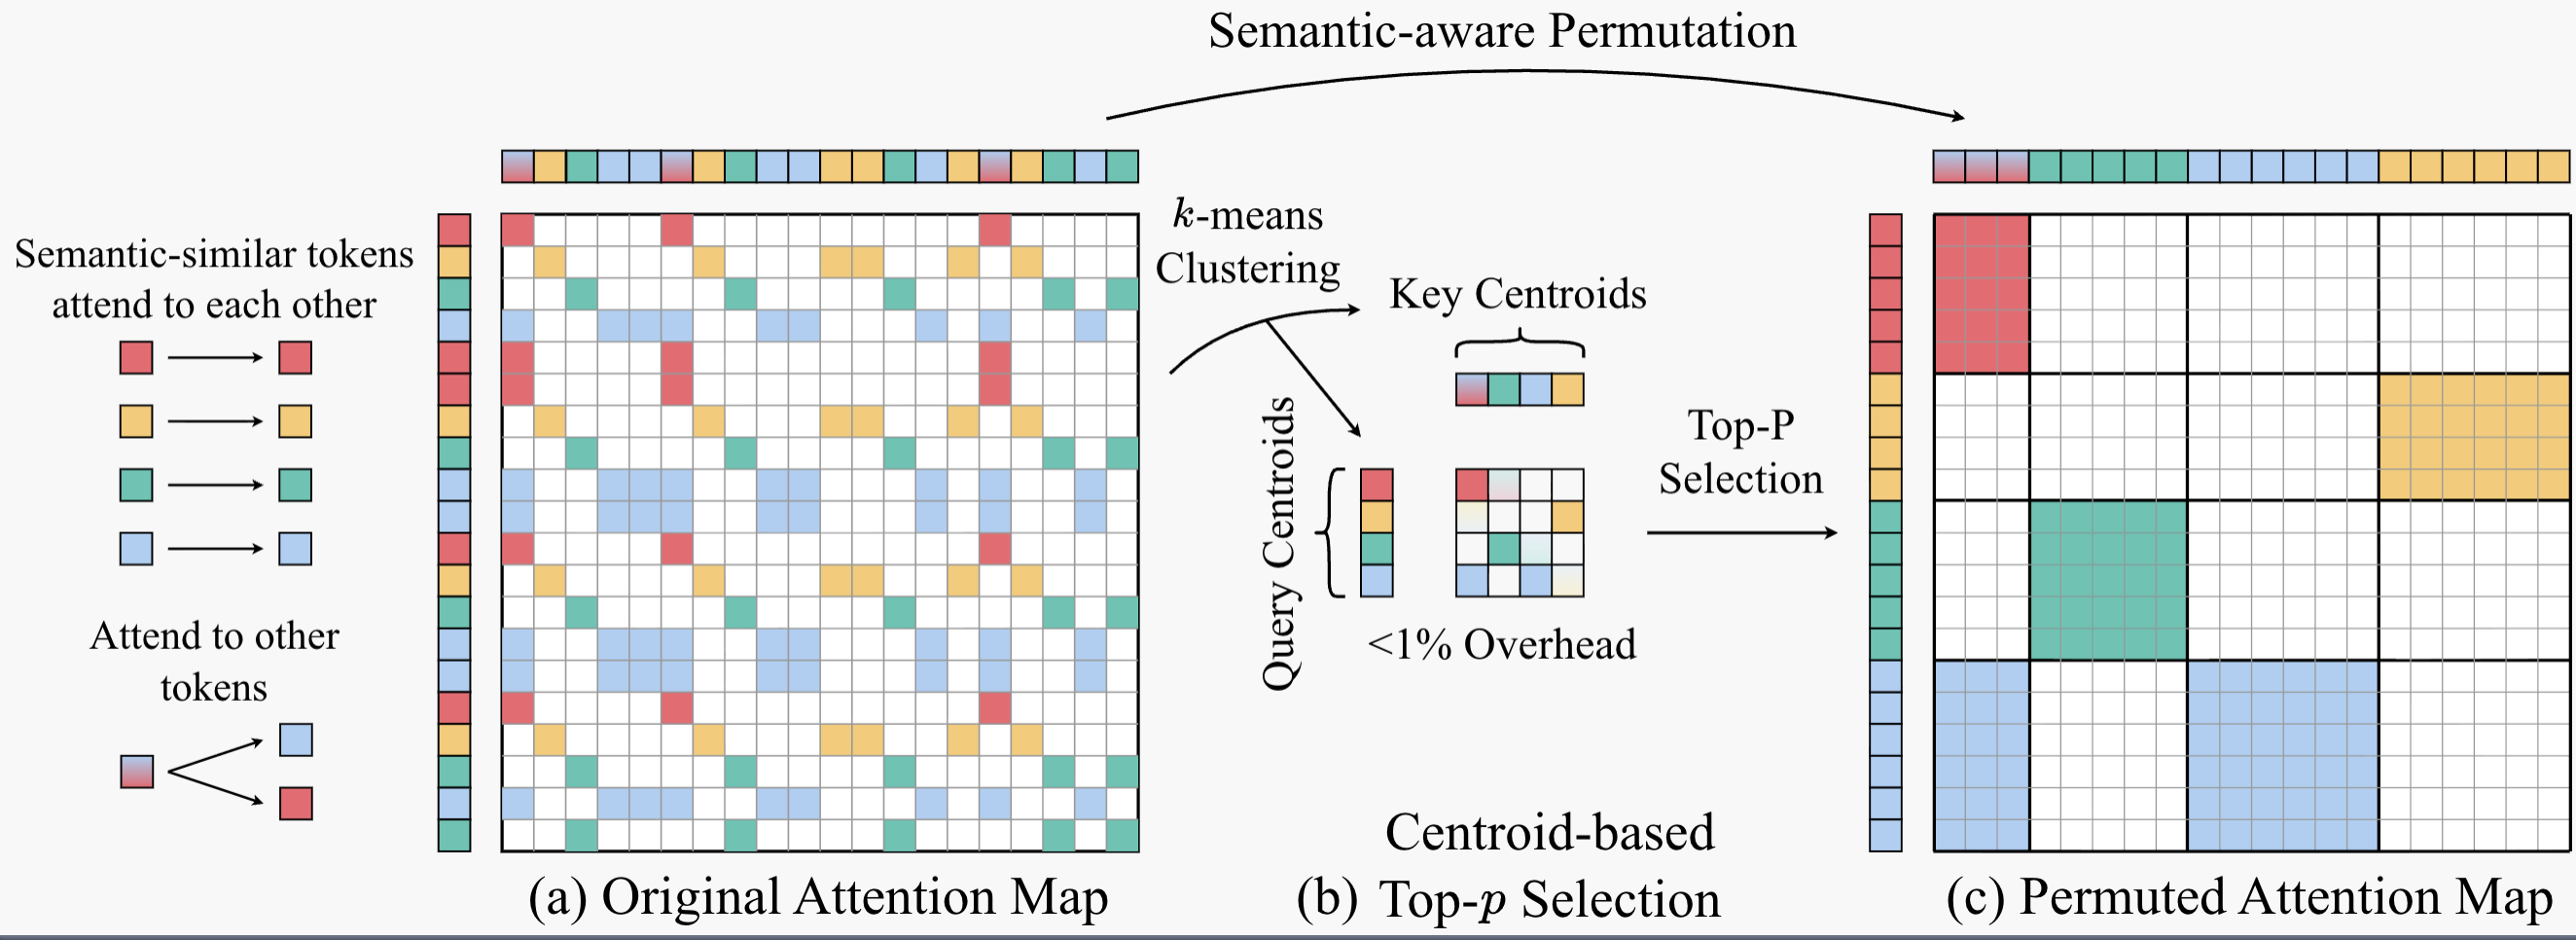
Sparse VideoGen2
Accelerating video generation with sparse attention via semantic-aware permutation.
NeurIPS 2025
Long Video
Sparse Attention
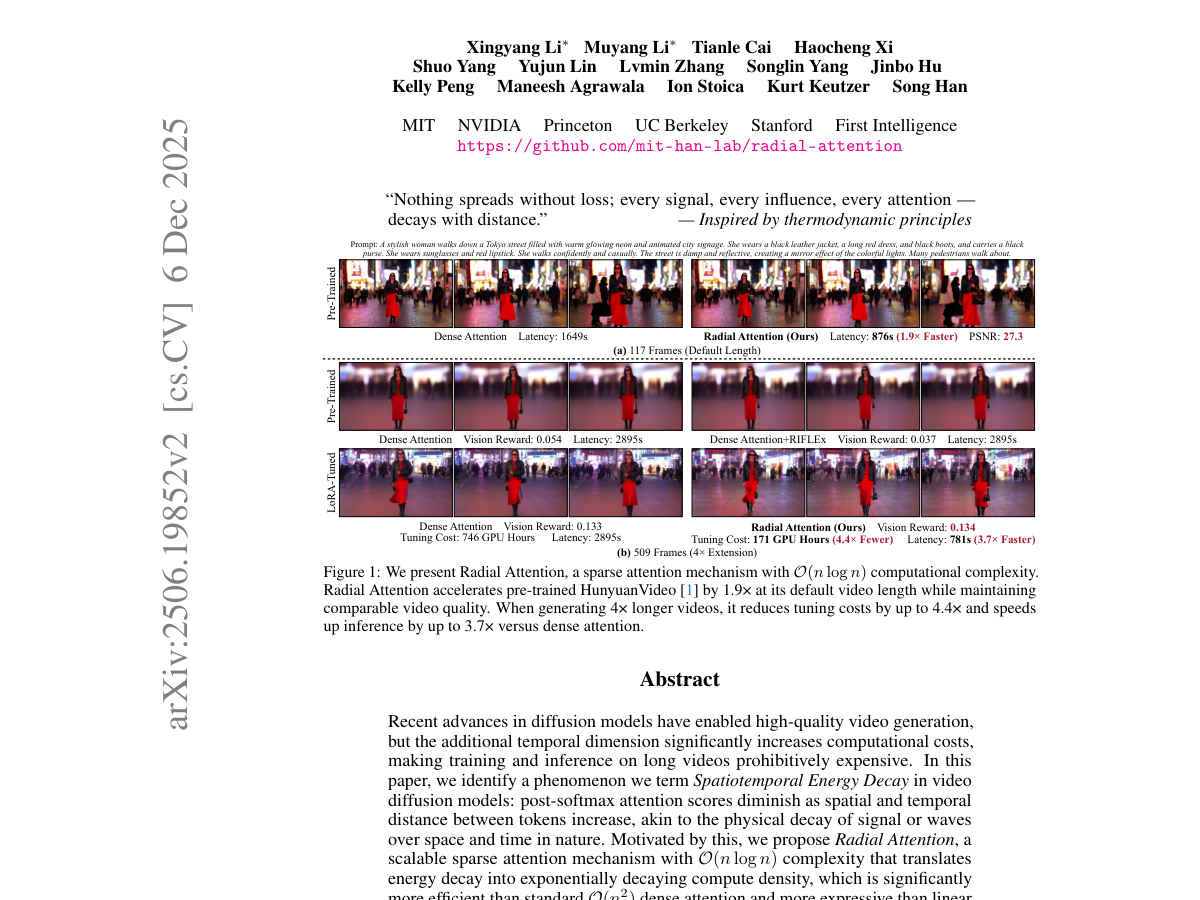
Radial Attention
O(n log n) sparse attention with energy decay for long video generation.
ICML 2025
Sparse Attention
Video Generation
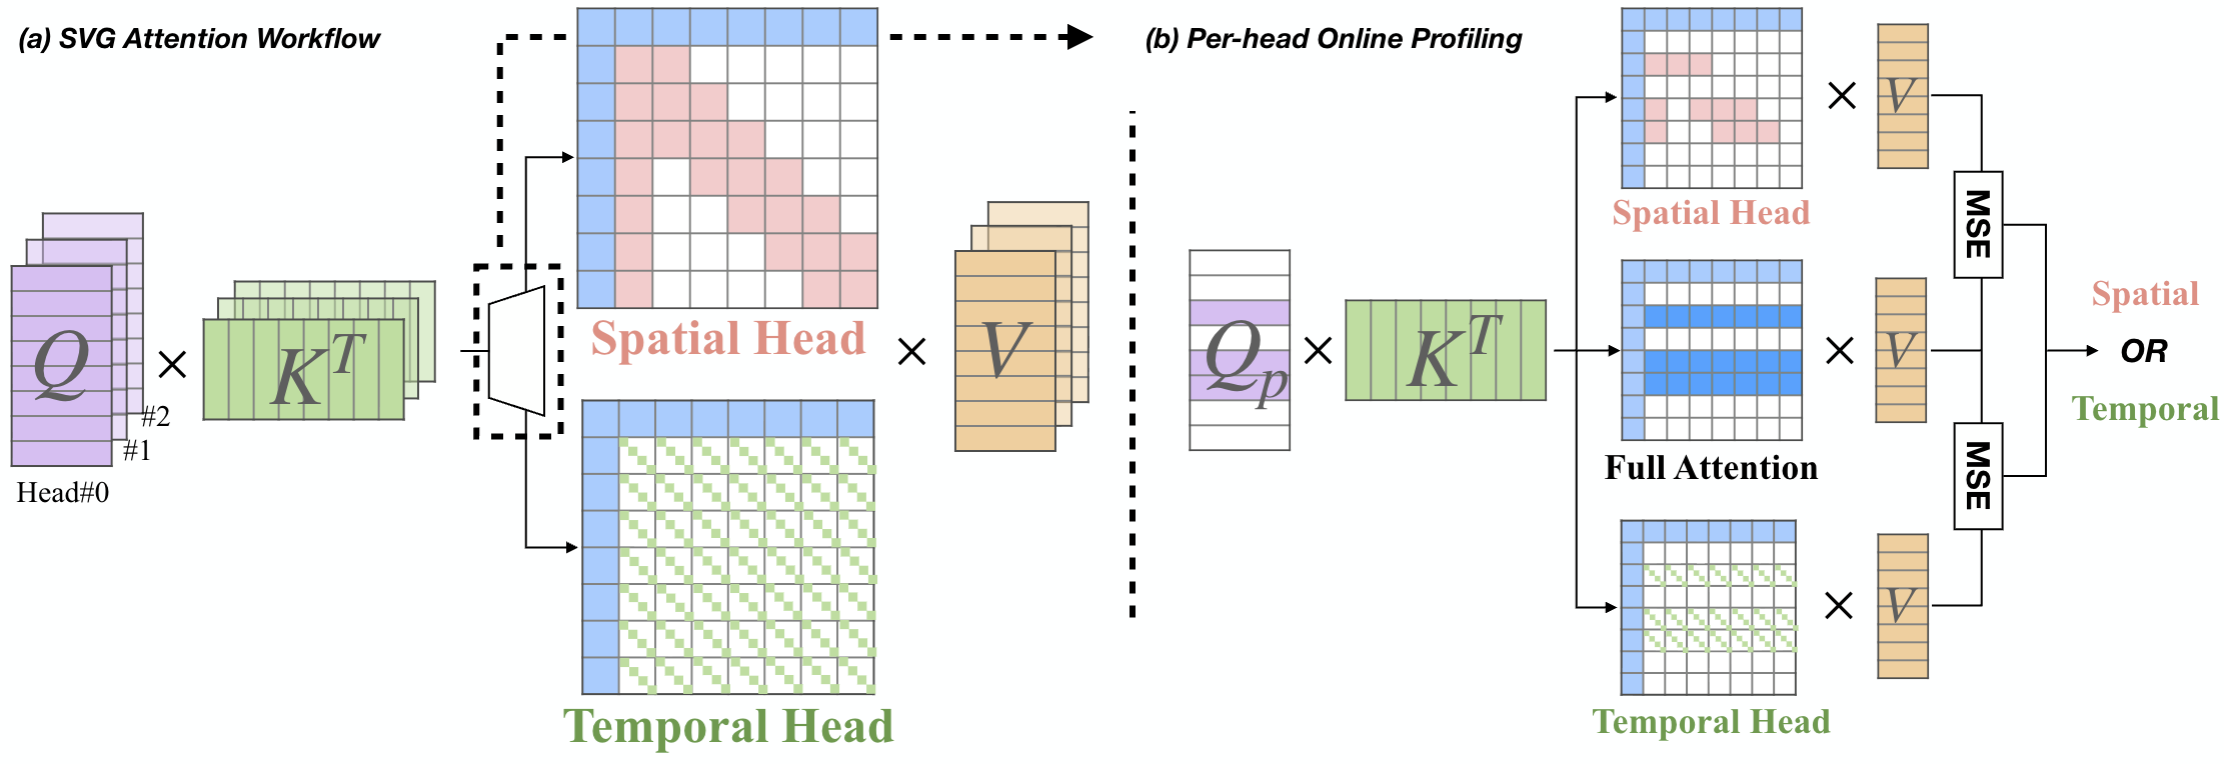
Sparse VideoGen
Accelerating video diffusion transformers with spatial-temporal sparsity.
OSDI 2026
GPU Sharing
Multi-LLM Serving
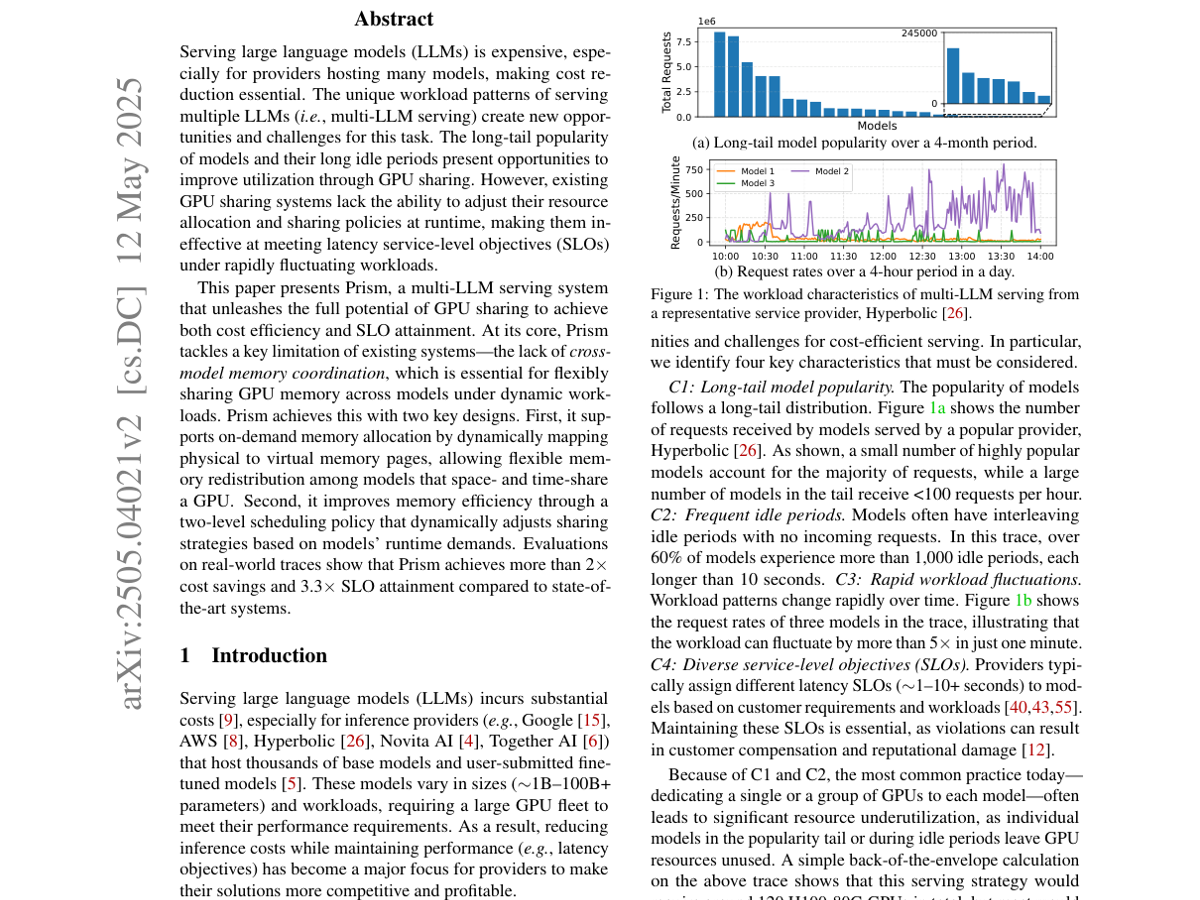
Prism
Unleashing GPU sharing for cost-efficient multi-LLM serving.

OSDI 2026
GPU Networking
Transport Layer
UCCL
An extensible software transport layer for GPU networking.
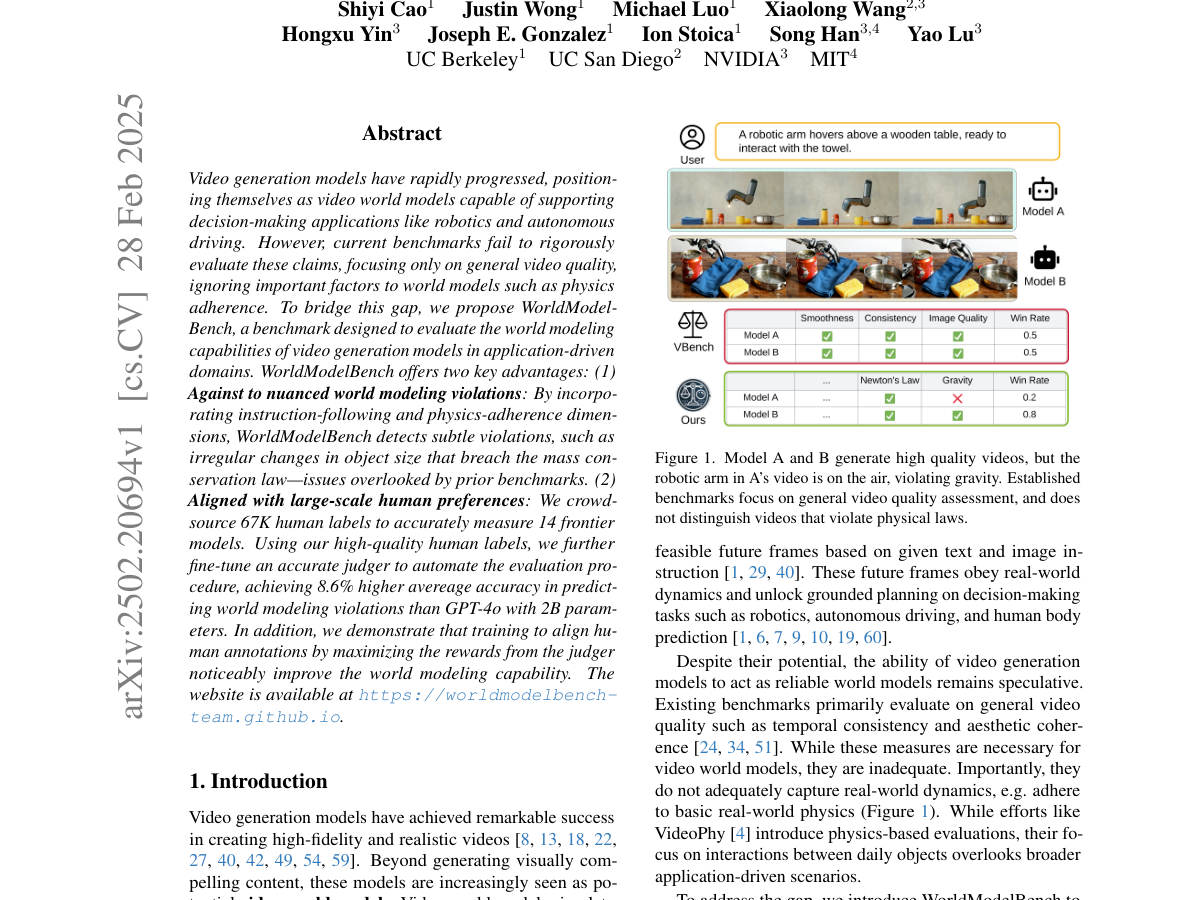
NeurIPS 2025
Benchmark
World Models
WorldModelBench
Judging video generation models as world models.
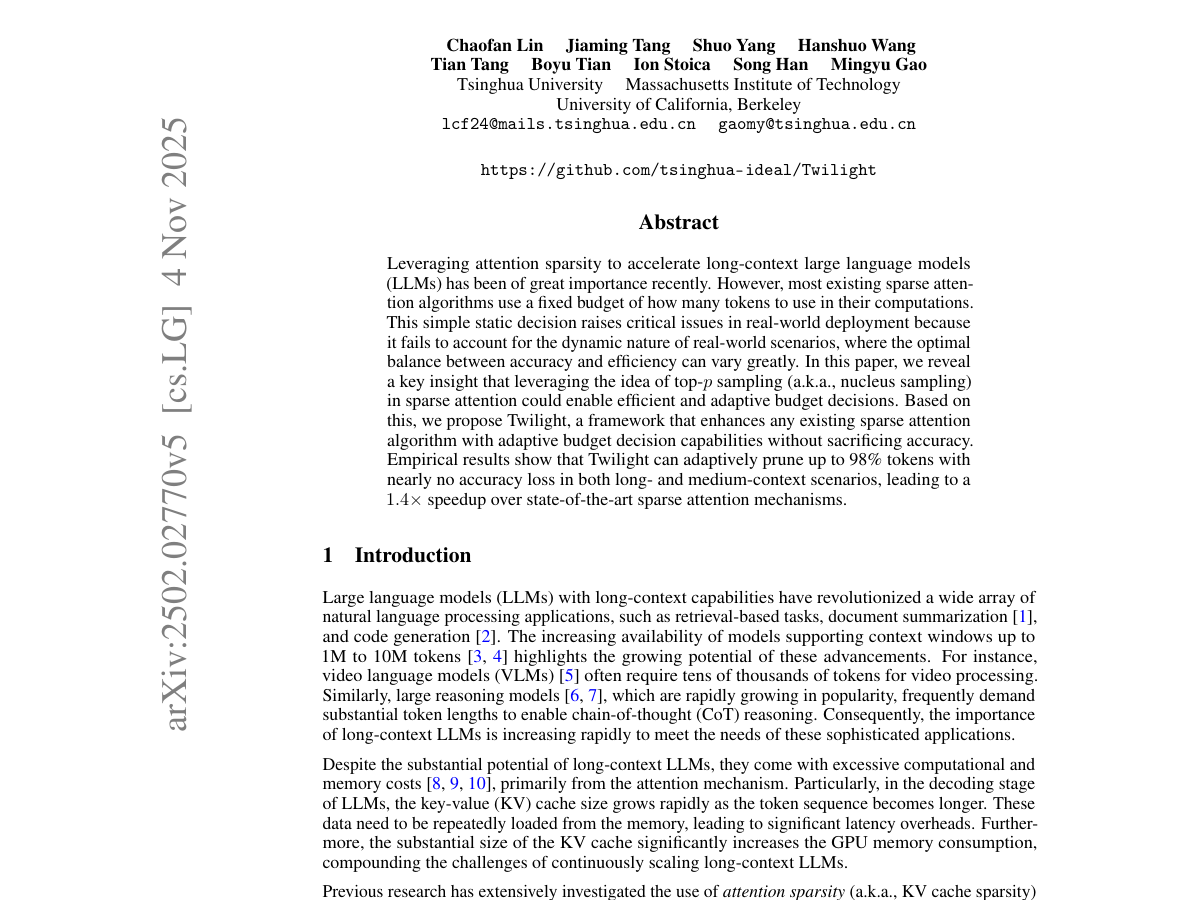
NeurIPS 2025 Spotlight
Adaptive Sparsity
Long Context
Twilight
Adaptive attention sparsity with hierarchical top-p pruning.
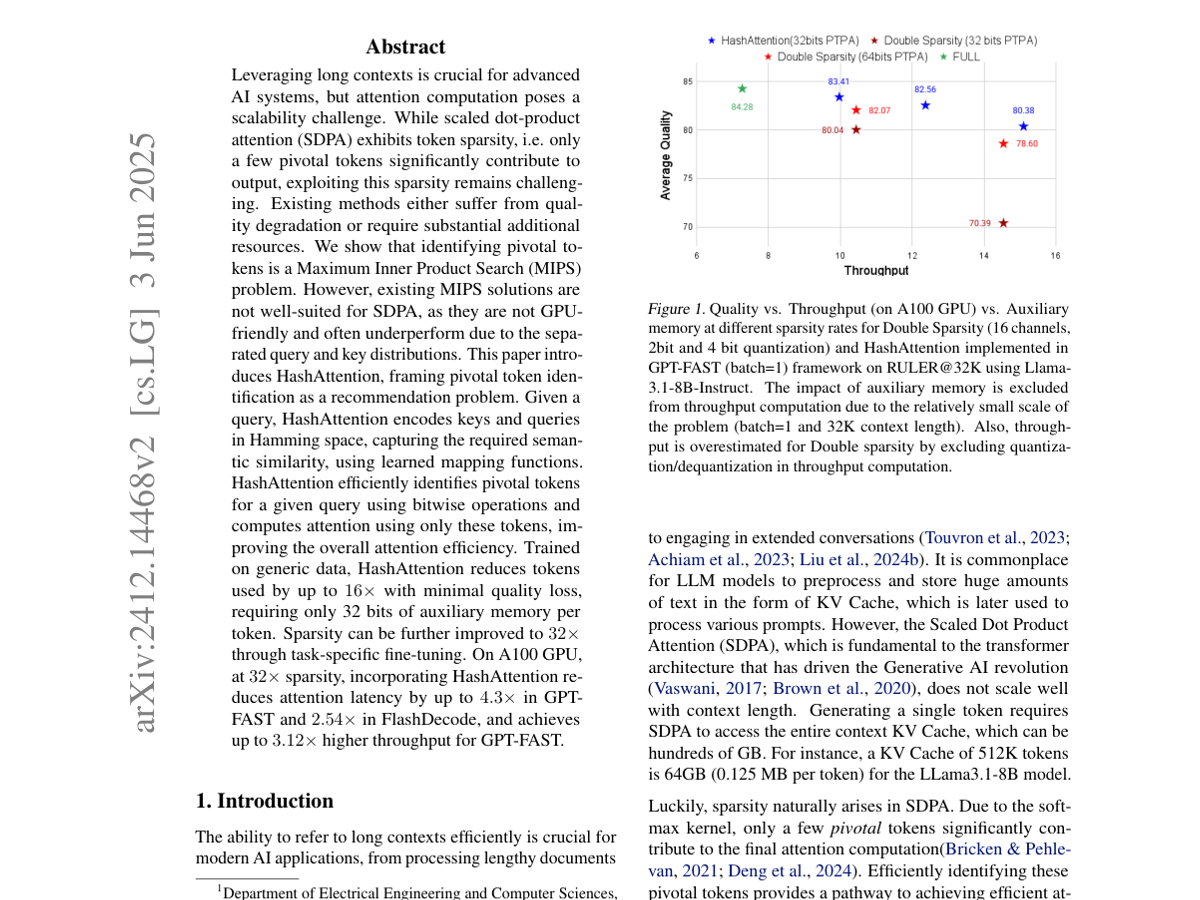
ICML 2025
Semantic Sparsity
Sparse Attention
HashAttention
Semantic sparsity for faster inference.
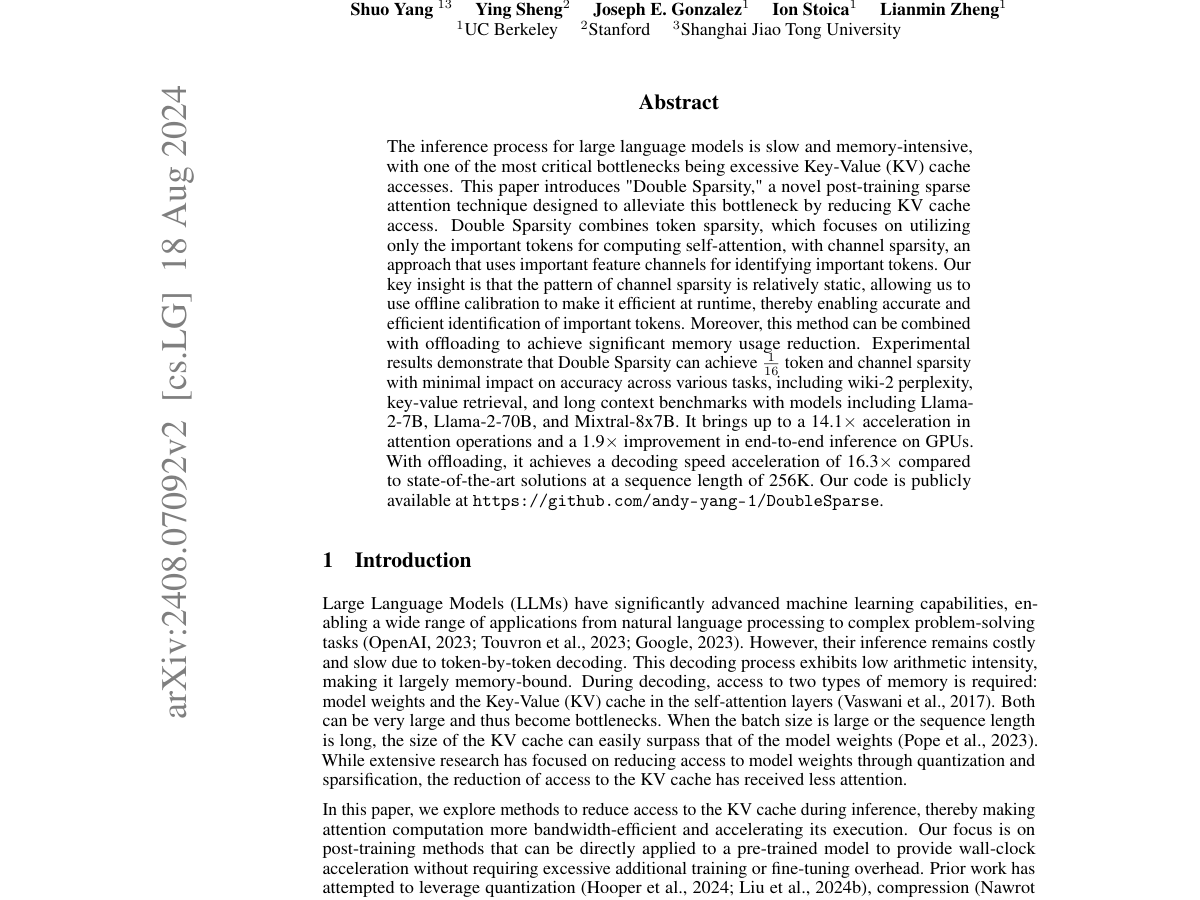
Sparse Attention
KV Cache
LLM Inference
Post-Training Sparse Attention with Double Sparsity
Sparse attention for reducing KV-cache bandwidth in LLM inference.
MLSys 2024
LoRA Serving
CUDA Kernels
S-LoRA
Serving thousands of concurrent LoRA adapters.
Data Quality
Benchmark Contamination
Evaluation
Rethinking Benchmark and Contamination for Language Models with Rephrased Samples
Decontamination and benchmark overlap analysis for language models.