Hi, my name is

Shuo Yang.

I build full-stack machine learning systems.

I am a Ph.D. student in EECS at UC Berkeley, advised by Ion Stoica. I work on full-stack machine learning systems, from kernel optimization and efficient system design to text and multimodal algorithms, with the goal of making modern AI workloads efficient on real hardware.

Shuo Yang profile image

About

I am a member of Sky Computing Lab and LMSYS. My work spans the full stack of machine learning systems: kernel optimization at the hardware-software boundary, efficient system design for large-scale inference and generation, and text and multimodal algorithms that benefit from those systems advances.

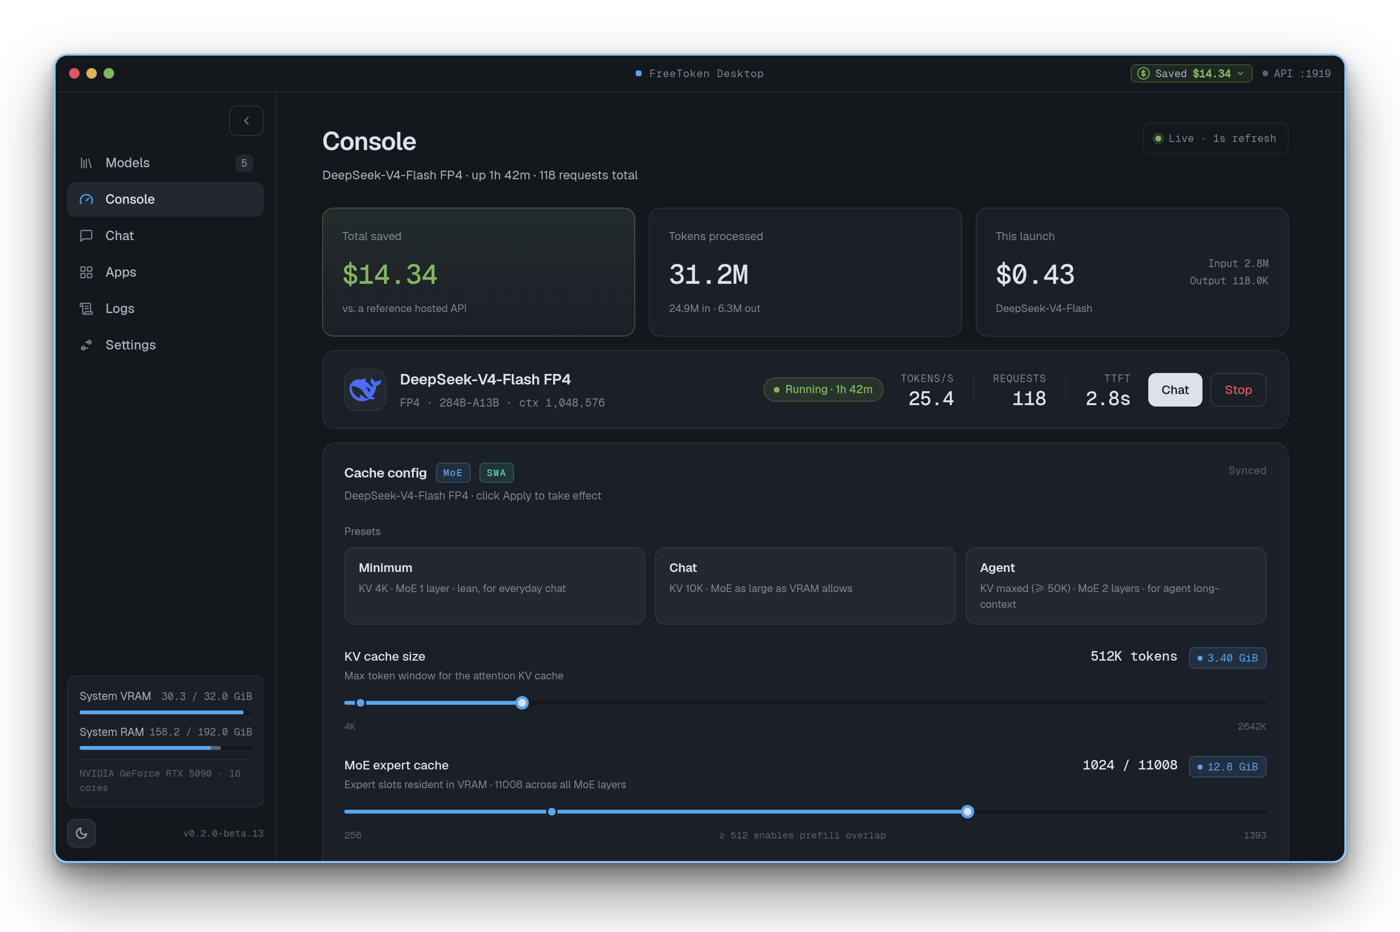
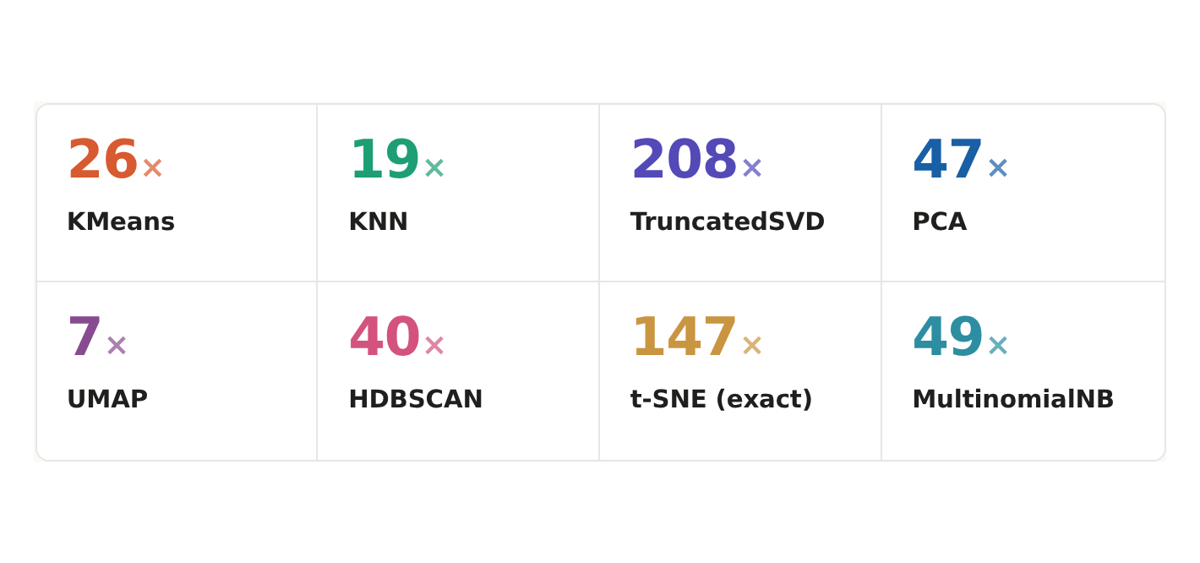
I am especially interested in algorithm-system co-design: building methods that are not only theoretically appealing, but also practical and efficient when deployed at scale. Recently, I built FreeToken, an edge-native MoE serving engine that runs 290B+ frontier models on consumer GPUs, and FlashLib, a GPU library that turns classical ML operators such as K-Means, KNN, PCA, and SVD into fast online primitives. Earlier work covers LLM serving, sparse attention, and efficient video generation.

Recent highlights include the Amazon AI PhD Fellowship, a research scientist internship at Amazon Neuron Science, and a research internship at Meta.

Previously, I graduated from the ACM Honors Class at Shanghai Jiao Tong University.
News

2026.09 Flash-KMeans was accepted to NeurIPS 2026.
2026.07 Released FreeToken, an edge-native MoE serving engine that runs 290B+ frontier models on consumer GPUs. It has passed 13k GitHub stars.
2026.05 Released FlashLib, a GPU library of classical ML operators with up to 208x speedup over cuML.
2026.05 Quant VideoGen was accepted to ICML 2026.
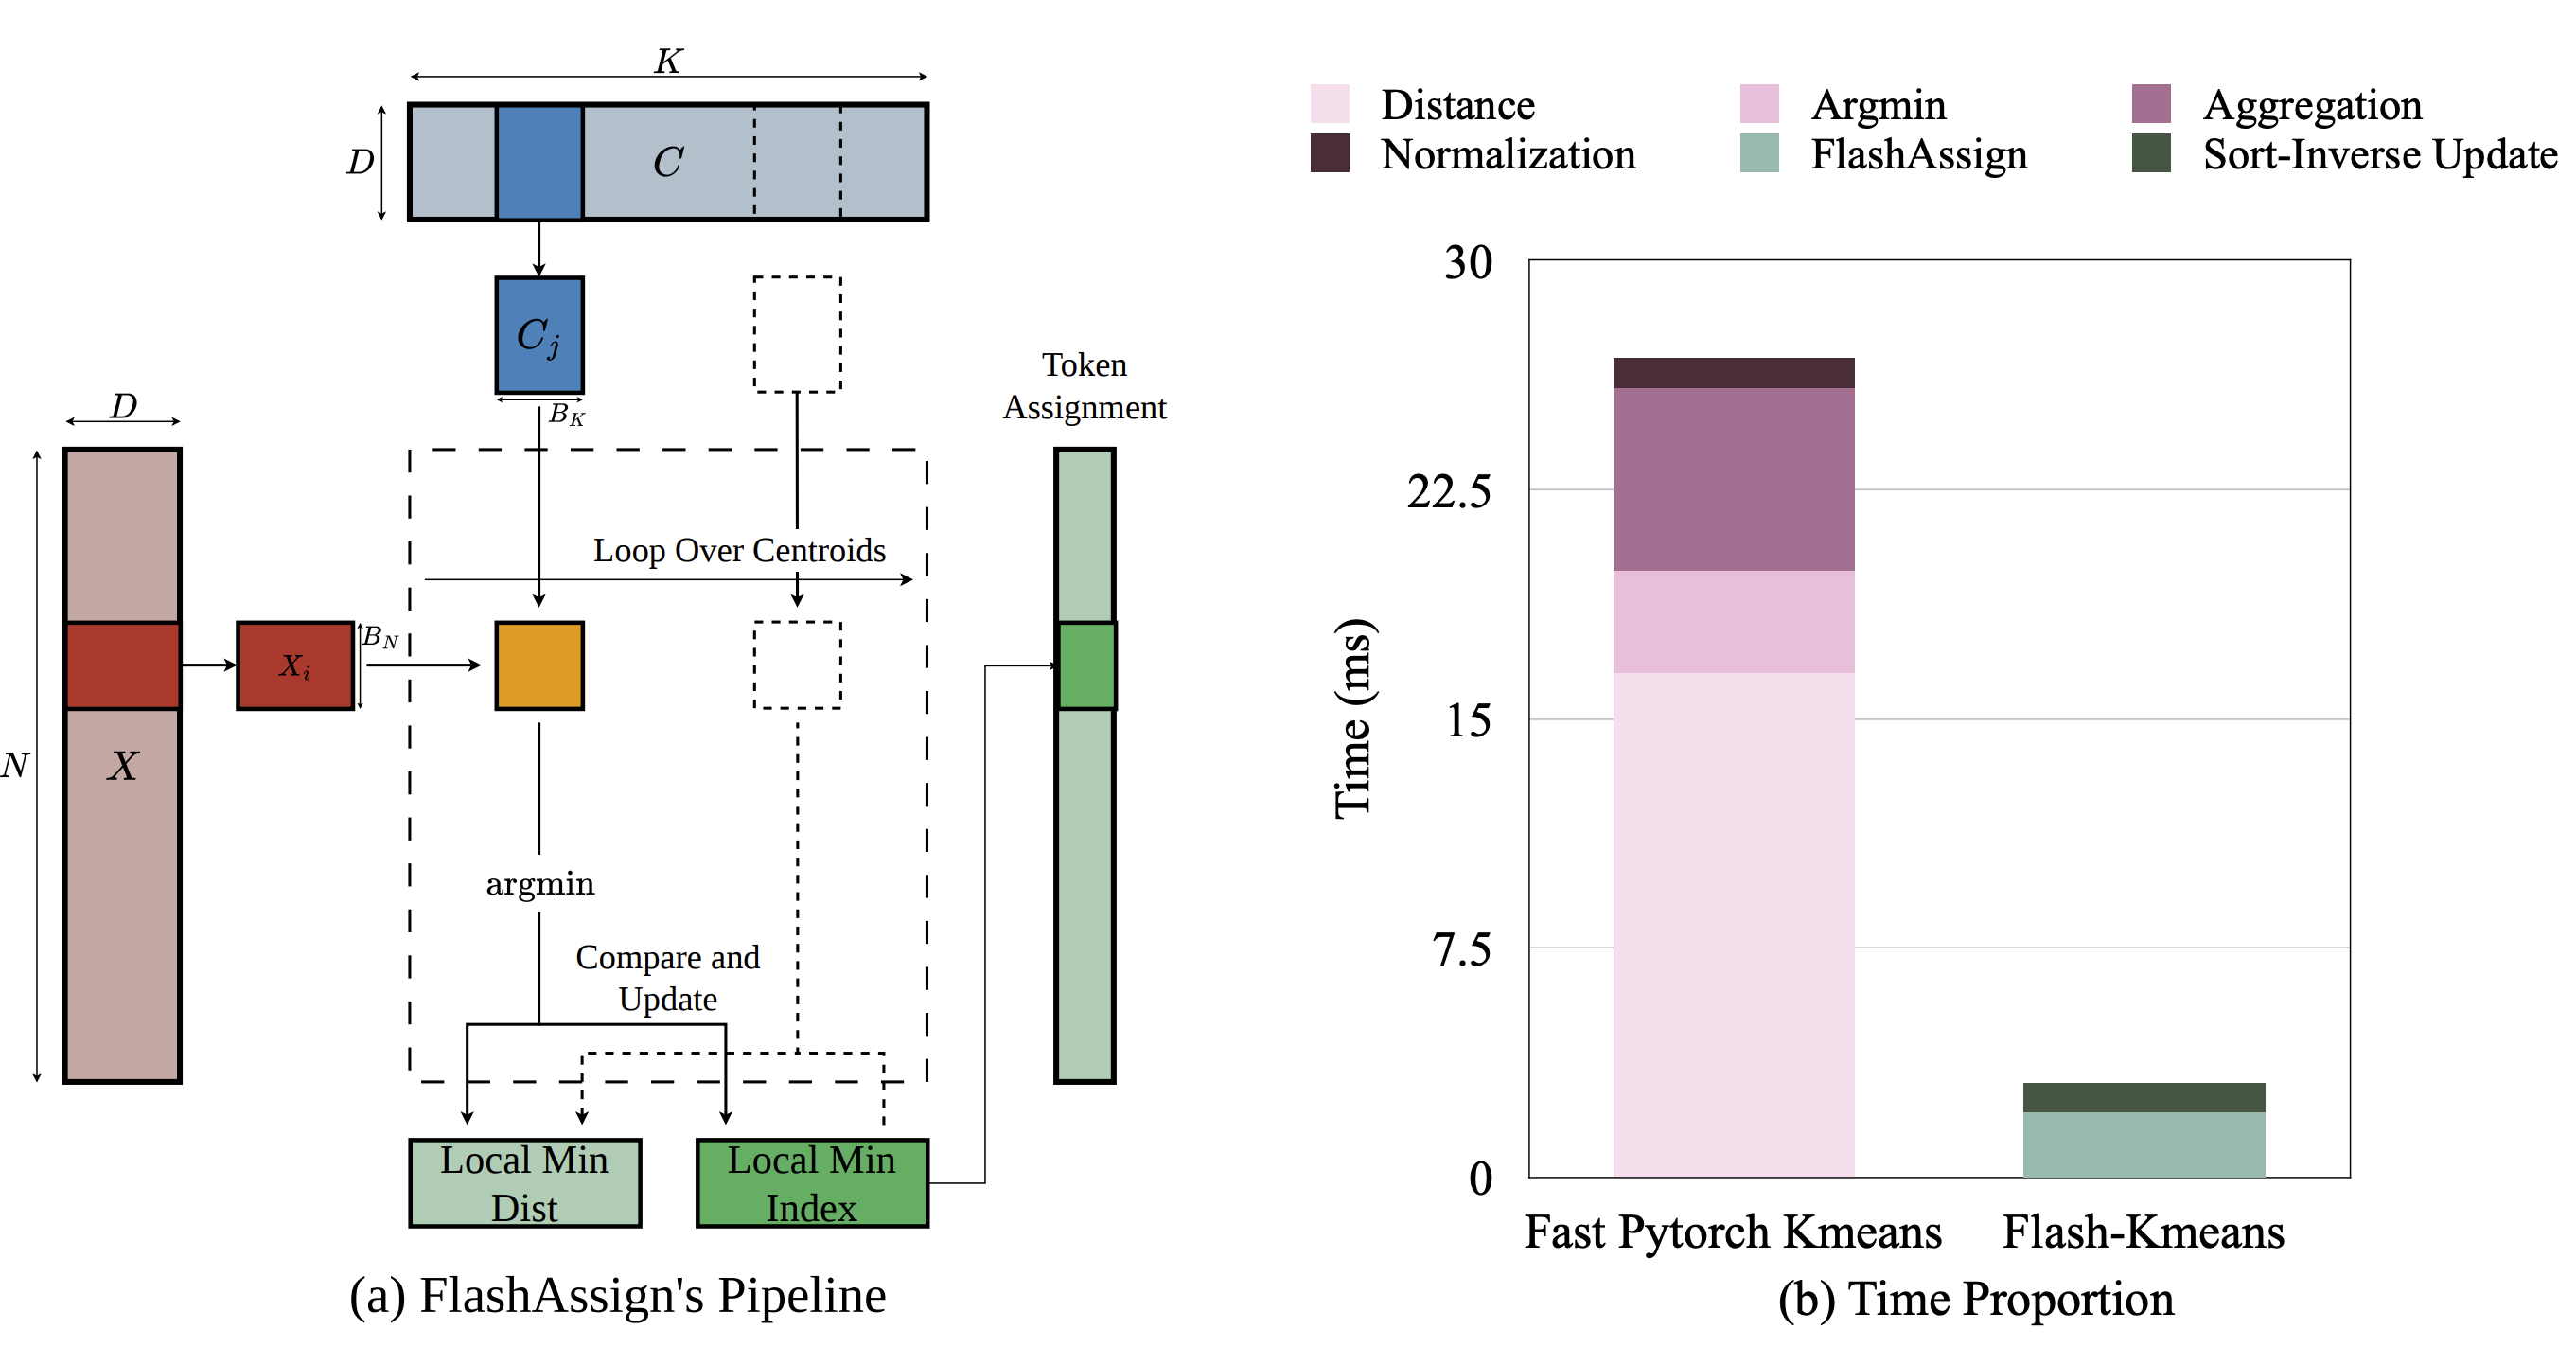
2026.03 Released Flash-KMeans, an exact batched K-Means primitive with Triton GPU kernels.
Older news
2026.02 I will join Meta as a research intern in summer 2026.
2025.09 Sparse VideoGen2 was accepted to NeurIPS 2025 as a Spotlight paper.
2025.05 I joined Amazon Neuron Science as a Research Scientist Intern, working on efficient high-quality long video generation.
2025.05 Sparse VideoGen was accepted to ICML 2025.
2025.04 I received the Amazon AI PhD Fellowship.

Selected Work

FreeToken
13.8k stars Edge Serving MoE
FreeToken
An edge-native MoE serving engine that runs 290B+ frontier models locally on consumer GPUs.
FlashLib
GPU Library Classical ML Operators Agent-Native API
FlashLib
Flash-style GPU kernels for classical ML operators, up to 208x faster than cuML.
Flash-KMeans
NeurIPS 2026 Fastest K-Means 700+ stars
Flash-KMeans
Fast and memory-efficient exact K-Means designed as a systems primitive.
StreamDiffusionV2
MLSys 2026 Best Paper Interactive Video Streaming System
StreamDiffusionV2
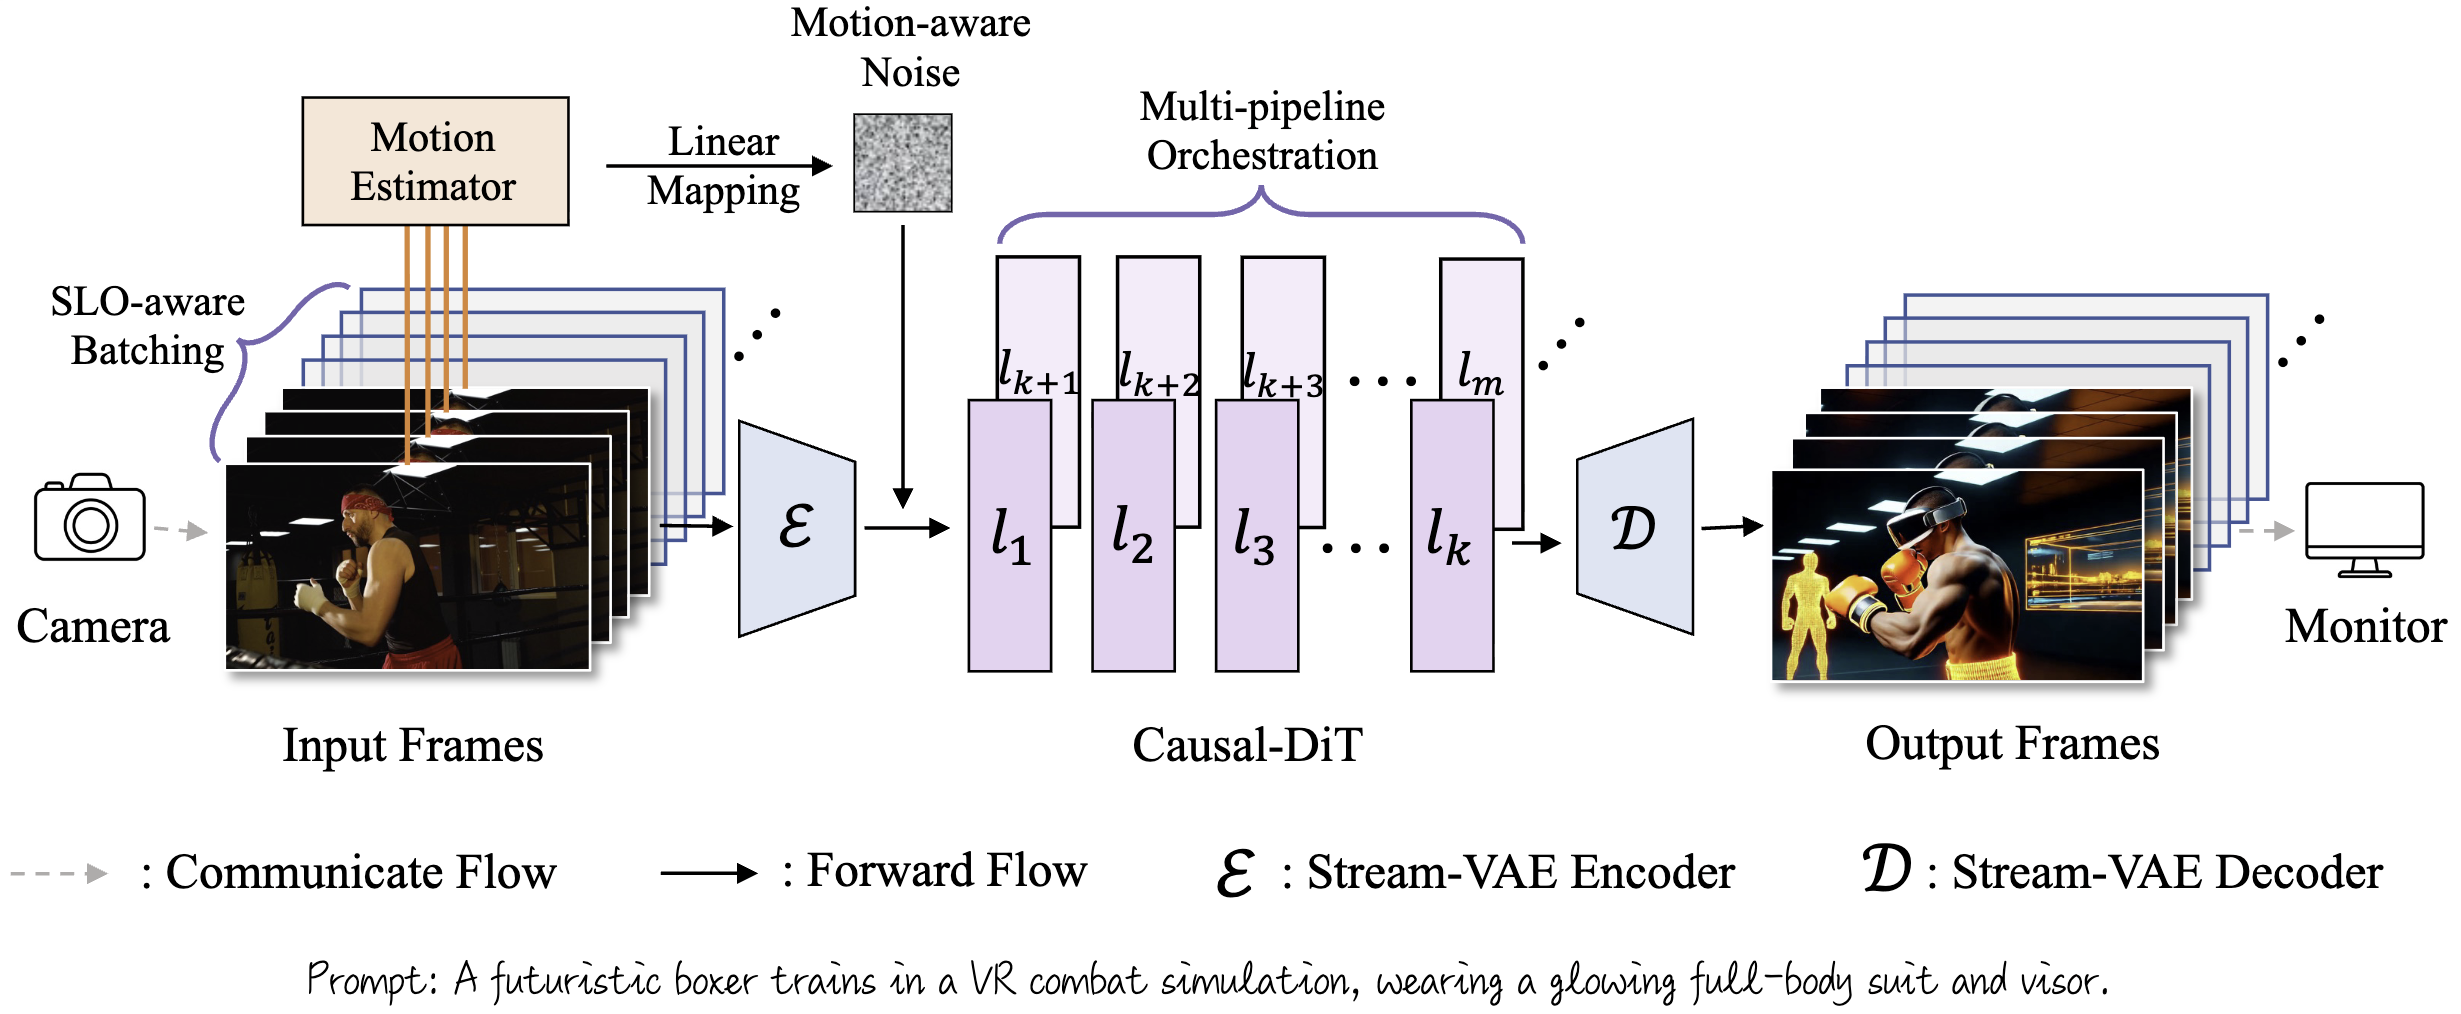
A streaming system for dynamic and interactive video generation.
Quant VideoGen
ICML 2026 Quantization KV Cache
Quant VideoGen
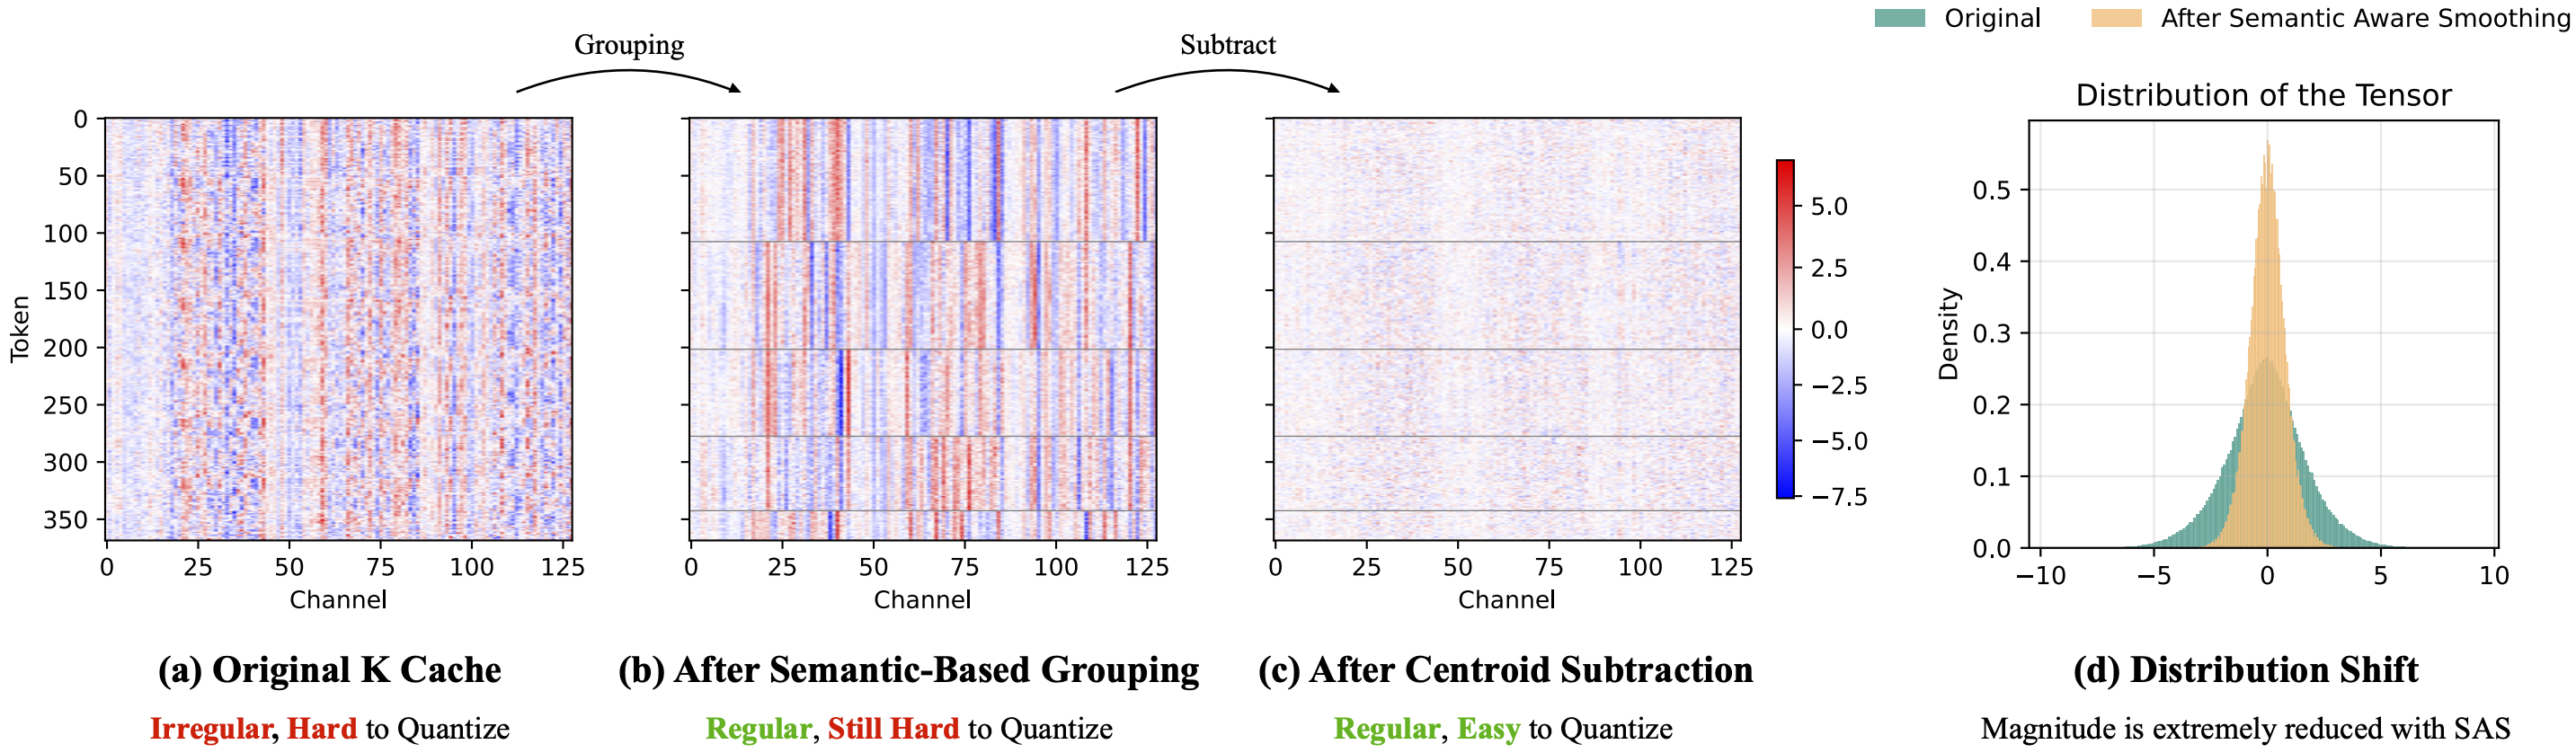
Long-video generation via 2-bit KV-cache quantization.
Sparse VideoGen2
NeurIPS 2025 Spotlight Semantic Permutation Video Generation
Sparse VideoGen2
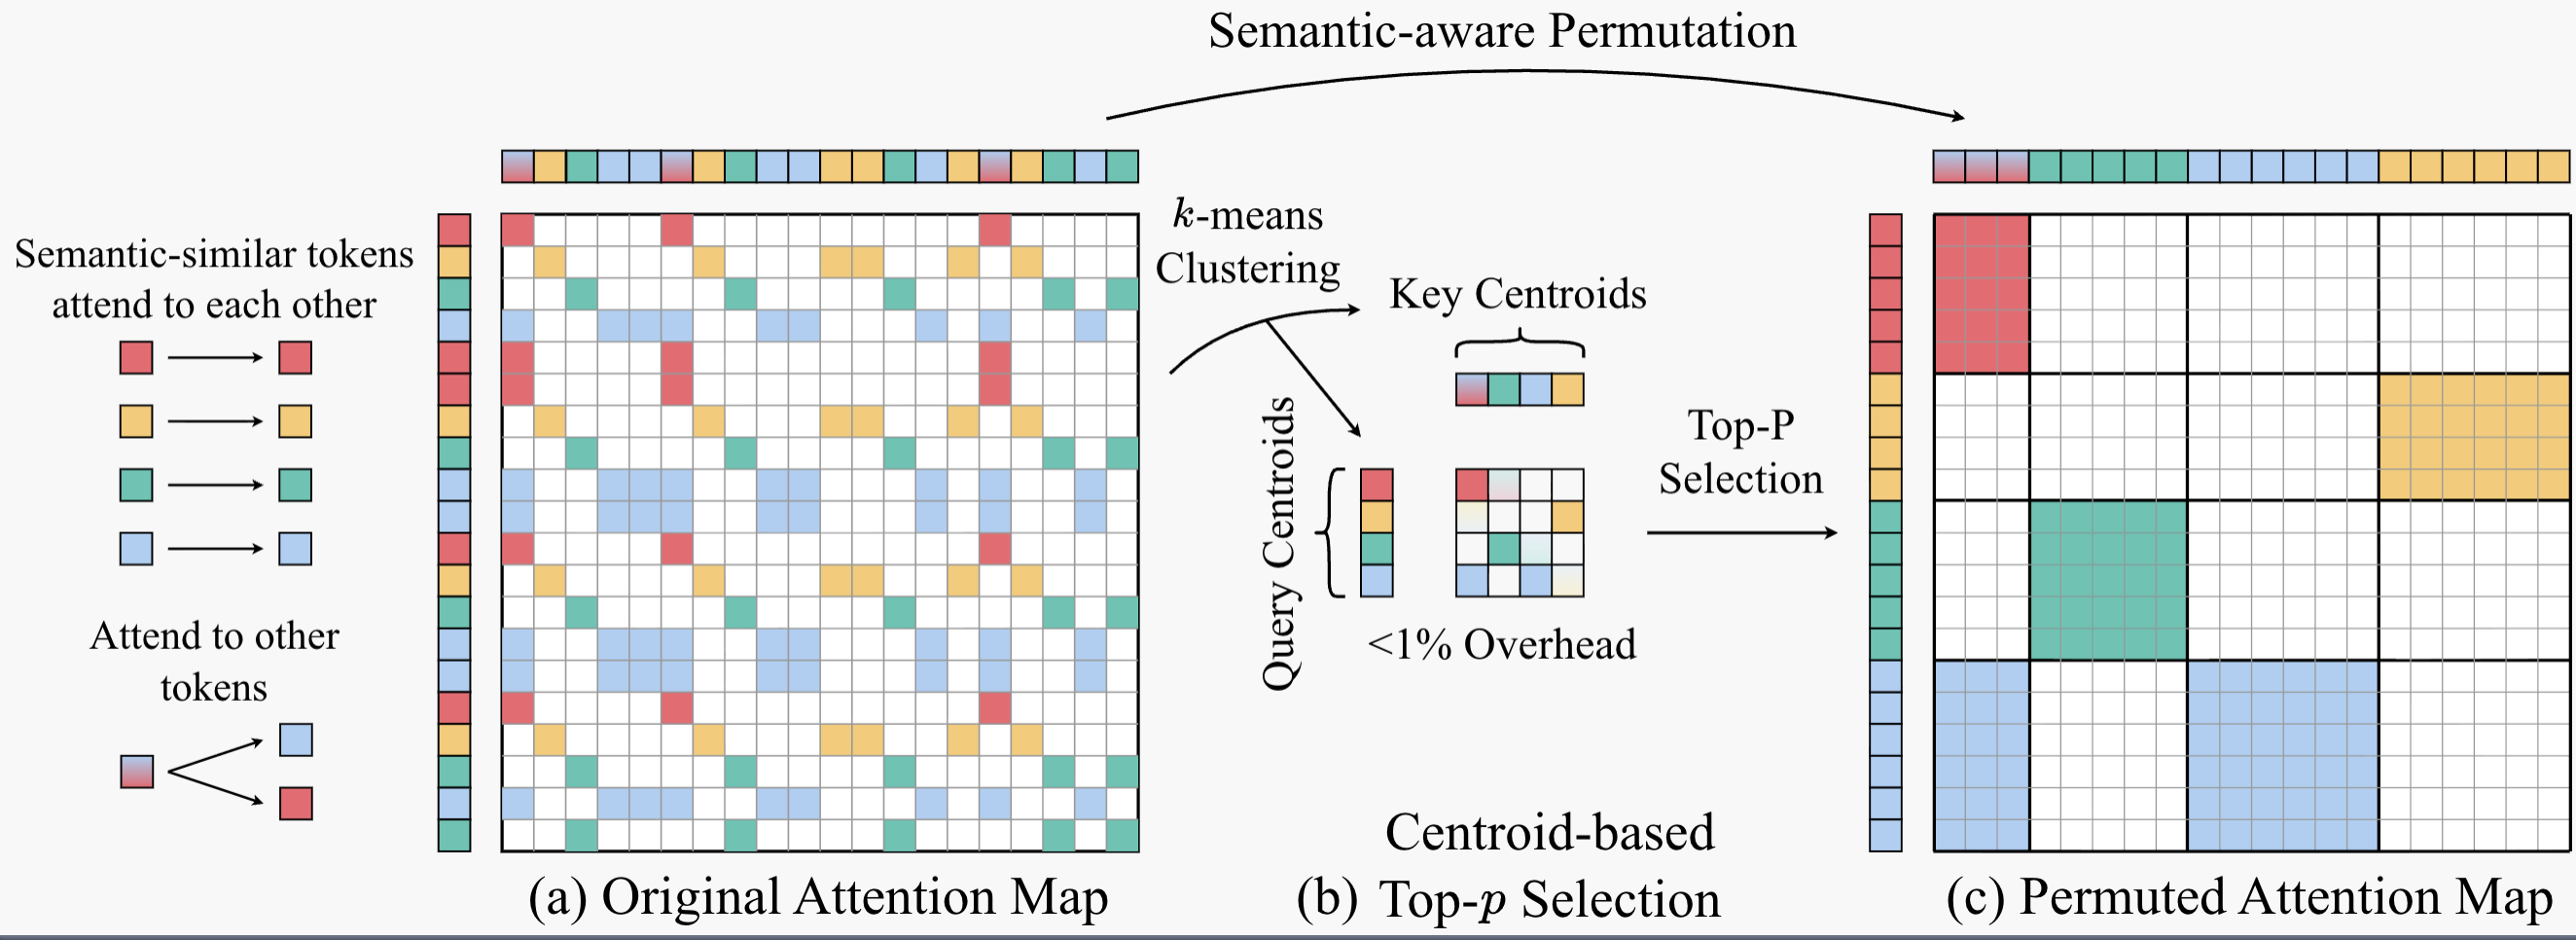
Semantic-aware permutation for efficient sparse attention in video generation.
Sparse VideoGen
ICML 2025 Sparse Attention Video Generation
Sparse VideoGen
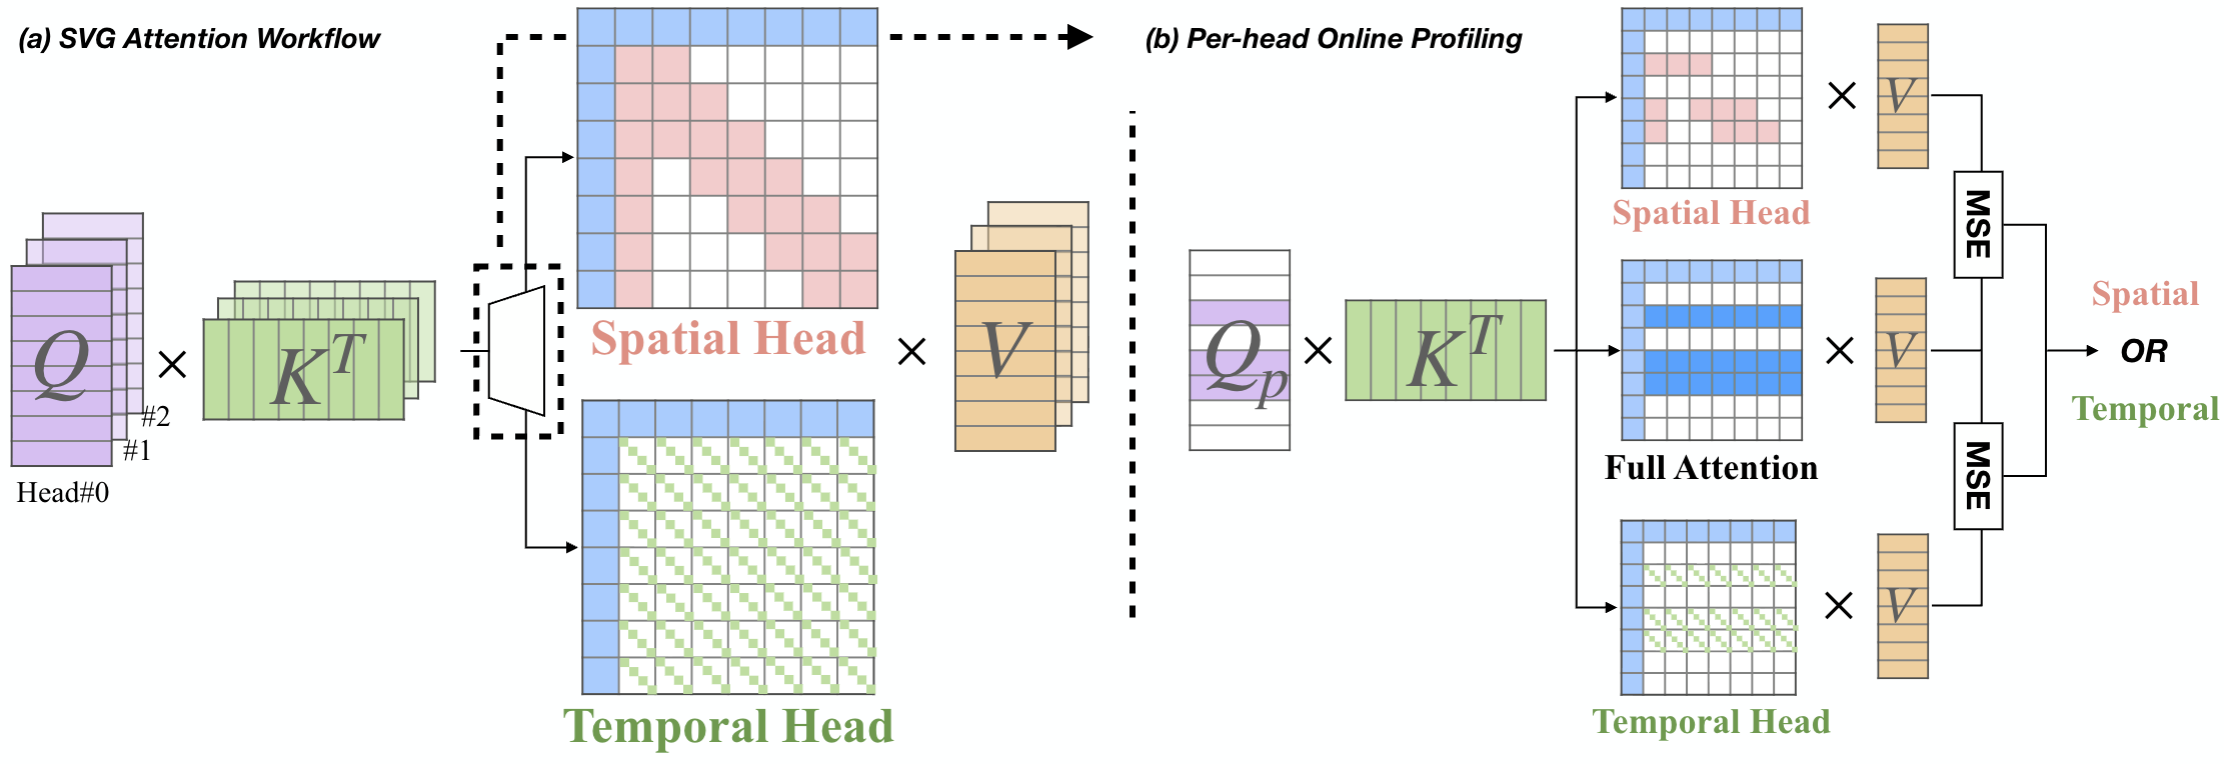
Accelerating video diffusion transformers with spatial-temporal sparsity.
BlendServe
ASPLOS 2026 Offline Inference LLM Serving
BlendServe
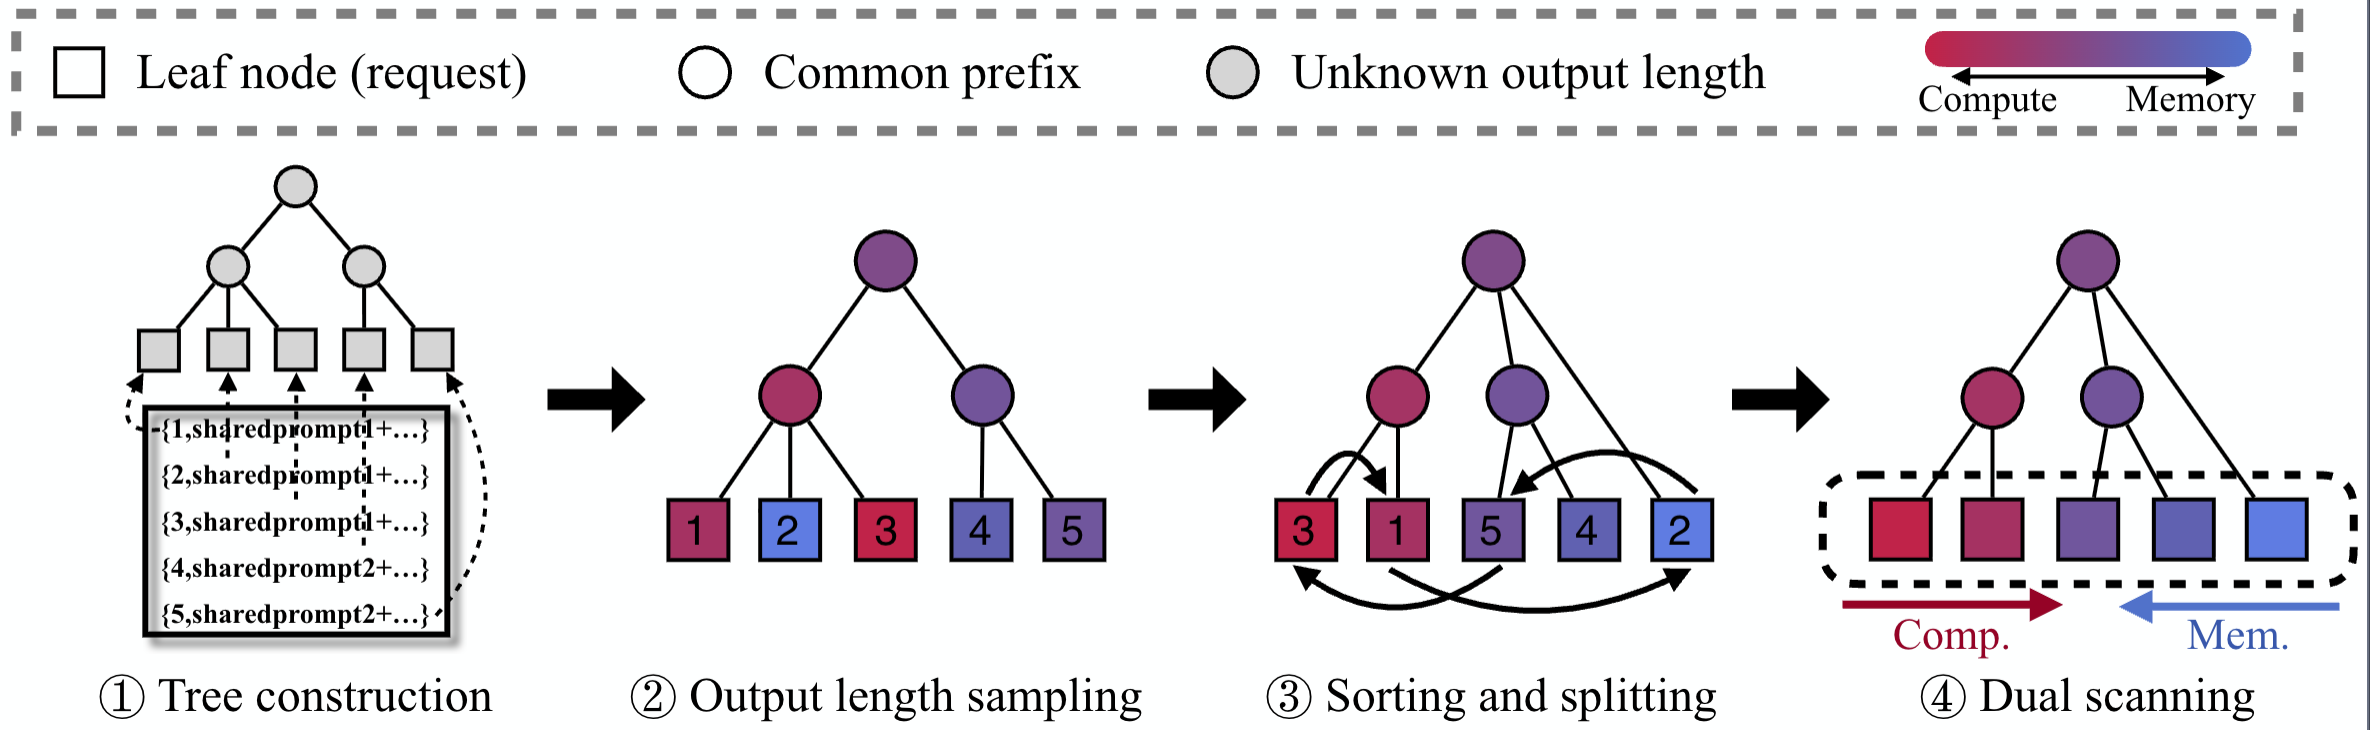
Resource-aware batching for offline inference of autoregressive large models.